1
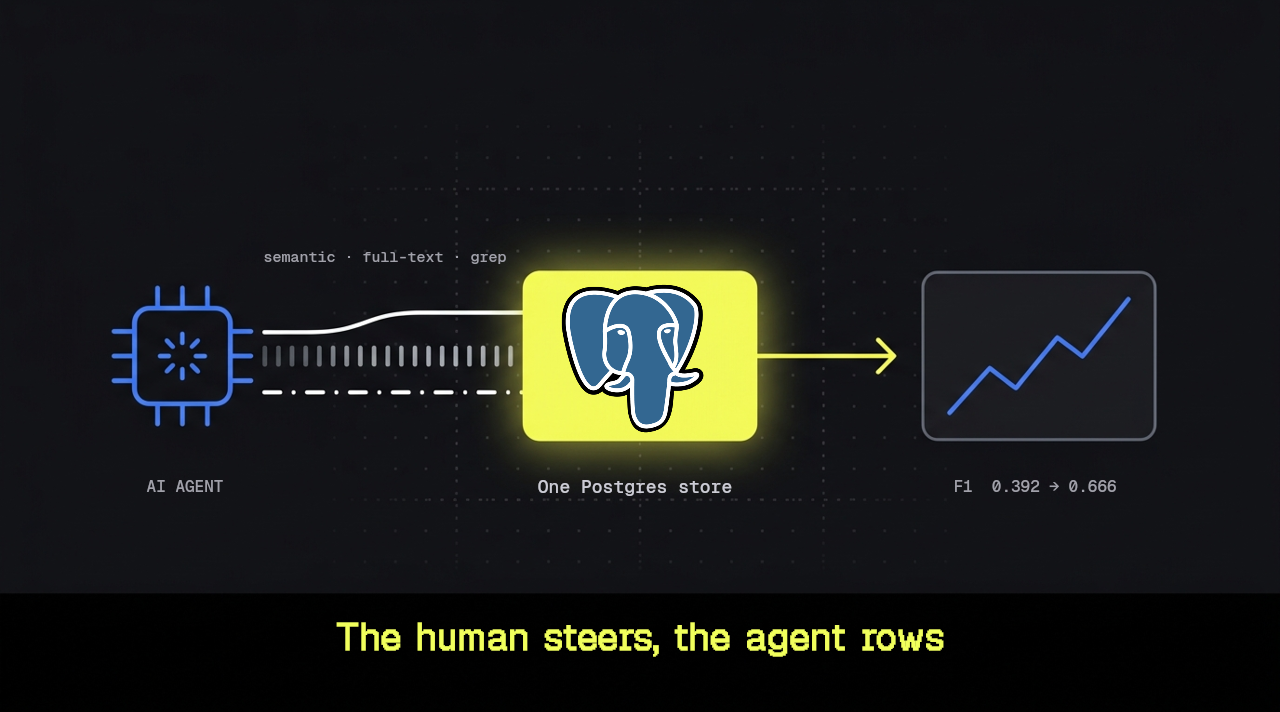
41 Experiments in 6 Days: What the Human Was Actually For
Timescale used an AI agent to run 41 experiments in six days, improving LLM conversational memory on the LoCoMo benchmark. The core insight is that humans are crucial for validating metrics and objectives, preventing the agent from optimizing against flawed measurements.
Timescaletigerdata.com8 min