Related reading
UTF-8000: Unlimited UTF-8
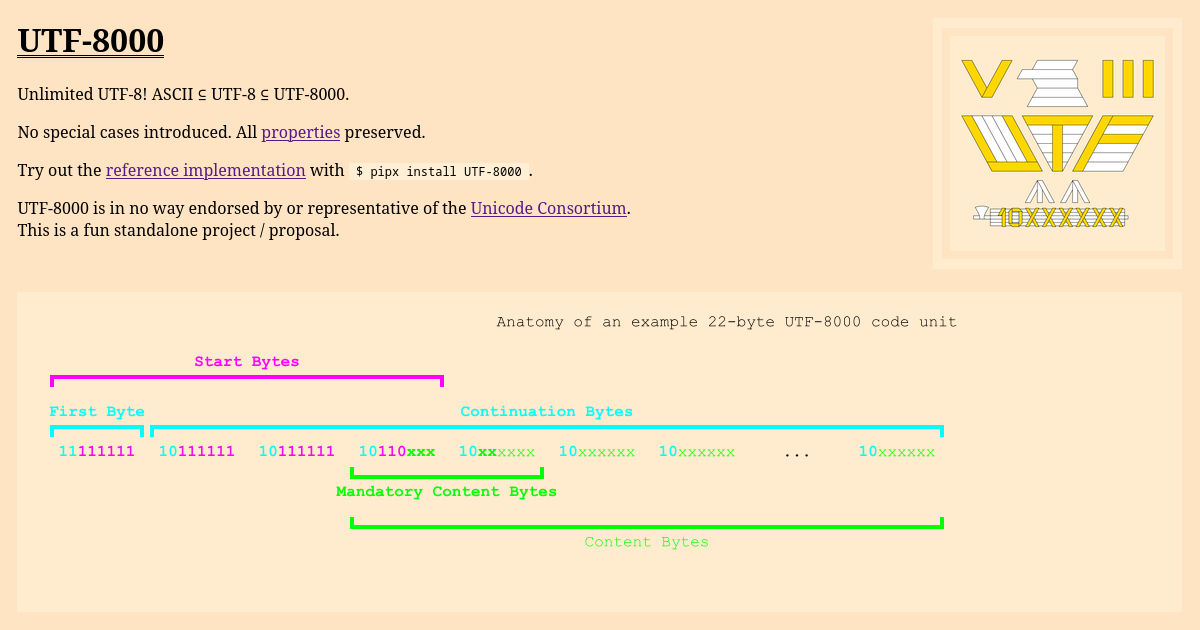
A speculative proposal for an “UTF‑8000” encoding that extends UTF‑8 to arbitrarily long code units. The post defines a new self‑synchronizing byte format, introduces terminology (first byte, start bits, continuation byte, etc.), and links to a reference implementation installable via pipx. No performance data, real‑world use cases, or rigorous analysis are provided.
Hacker News front pagejb2170.com90 minHN133118tokenizers v1: encode, decode and scaling, measured
Hugging Face has released `tokenizers` v1, a major performance update that achieves 3-30x faster encoding than v0.23 while maintaining identical output and API compatibility. Key optimizations include a SIMD-accelerated splitter, a thread-local word cache, and an allocation-free BPE merge loop, ensuring tokenization doesn't bottleneck ML workflows.
Hugging Facehuggingface.co10 minWangNet – 1.8 MB, zero-dependency Numberwang adjudication in 11 languages
Numberwang is a tiny character‑level CNN packaged as a 1.8 MB JSON model and a ~100‑line pure‑Python inference script that classifies numeric strings in eleven languages without any external dependencies. It reaches 88.9 % macro‑F1 on a held‑out set, but struggles with unseen arithmetic expressions.
Hacker News front pagegithub.com2 minreleaseHN18062