Hacker News front page90 min readintermediate
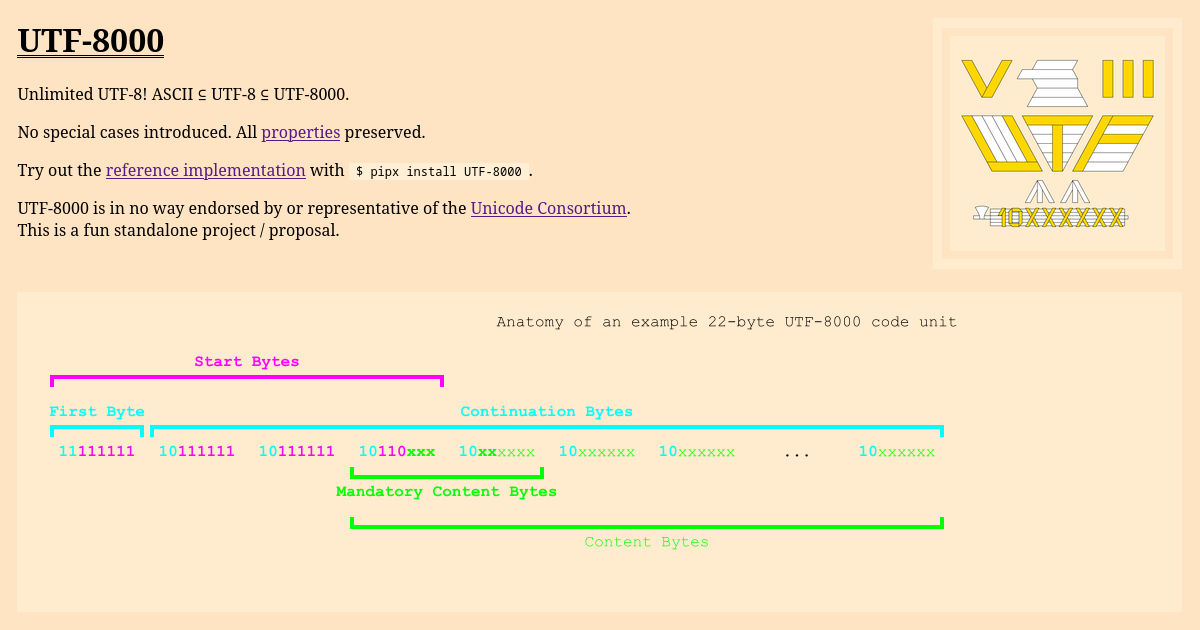
UTF-8000: Unlimited UTF-8
Summary
A speculative proposal for an “UTF‑8000” encoding that extends UTF‑8 to arbitrarily long code units. The post defines a new self‑synchronizing byte format, introduces terminology (first byte, start bits, continuation byte, etc.), and links to a reference implementation installable via pipx. No performance data, real‑world use cases, or rigorous analysis are provided.
- UTF‑8000 keeps UTF‑8’s self‑synchronizing property by using a prefix‑free tree of start‑bit patterns that can span many bytes.
- The design adds no new special‑case rules beyond the existing ASCII and 2‑byte overlong checks from UTF‑8.
- A reference implementation is available as a Python package, but the post does not discuss its internals or benchmarks.
Understanding how variable‑length encodings can be extended while preserving self‑synchronization is useful for anyone designing custom binary protocols or experimenting with Unicode extensions, but the post stops short of practical guidance.
4/10