proomt

Search

Search posts, papers, and topics

All posts

DuckDB5 min readintermediate
DuckDB and Hugging Face: Querying Datasets Directly

Summary

DuckDB adds an `hf://` protocol that lets you run SQL queries directly against datasets hosted on the Hugging Face Hub, eliminating the need to download files first. The post shows how to read single files, glob multiple files, pin revisions, and handle private datasets.

  • Use `SELECT * FROM 'hf://datasets/<user>/<repo>/file.parquet'` to query remote Hugging Face files without downloading.
  • Glob patterns (`*.parquet`) let you treat a whole dataset directory as one table and filter rows server‑side.
  • Pin to a specific commit or the `~parquet` branch with `@` to ensure reproducible, columnar scans.
  • Store a Hugging Face token via DuckDB Secrets Manager to access private or gated datasets.

ML engineers and data scientists who work with Hugging Face datasets can explore and subset data instantly, saving storage and pipeline overhead.

6/10
Related reading

  1. DuckDB Now Ships inside dbt v2

    dbt v2 (Rust‑based Fusion engine) now bundles a DuckDB adapter, removing the separate Python package. It adds built‑in catalog support (DuckLake, Iceberg), writes dbt’s information schema as Parquet for fast querying, provides native SQL comprehension with column‑level lineage, pins a specific DuckDB version (enabling native extension functions), and offers a migration path from v1.

    DuckDBduckdb.org7 min
  2. Glean Dictionary + DuckDB

    A short post describing how the Mozilla Glean Dictionary JSON can be exported into a DuckDB file via a simple ETL script, enabling SQL queries and notebook‑driven analysis of metric types and growth over time.

    Mozilla Automation Teamwrla.ch2 min
  3. A practical guide to cost optimization with Lakebase Postgres

    Lakebase’s separated storage‑compute architecture lets you cut database costs by syncing only the active data, picking the right sync mode, and right‑sizing compute so the hot working set fits in cache. Follow the blog’s concrete steps—materialized‑view subsets, snapshot vs triggered vs continuous sync, autoscale bounds, and connection‑pooling—to keep spend predictable without sacrificing perform…

    Databricksdatabricks.com12 min
  4. WAL + S3: Lakebase storage for the era of agents

    Neon's Lakebase Postgres redefines database storage by making the WAL the source of truth, stored on S3, rather than data files. This transaction-centric approach enables instant branching, time travel, and scalable, decoupled compute and storage for Postgres.

    Neonneon.com14 minHN4
  5. How Fountain rebuilt its data plane on ClickHouse Cloud to power Cue, the Frontline Superintelligence

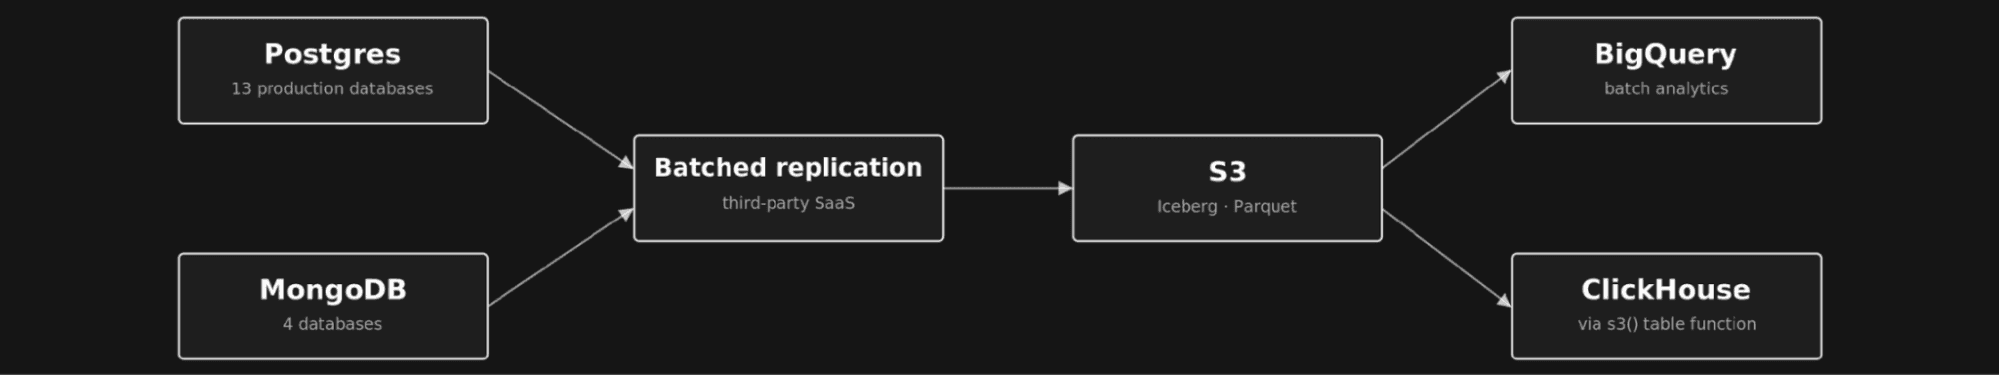
    Fountain replaced a multi‑vendor batch pipeline (Postgres + MongoDB → replication → S3/Iceberg → BigQuery/ClickHouse) with a single‑hop real‑time data plane built on ClickPipes and ClickHouse Cloud. CDC streams 13 Postgres and 4 MongoDB sources directly into ClickHouse, where native JSON, incremental materialized views, and role‑based access control provide sub‑second query latency, 66 % cost red…

    ClickHouseclickhouse.com9 min