proomt

Search

Search posts, papers, and topics

All posts

Simon Willison1 min readintermediate
Gemini Live audio

Summary

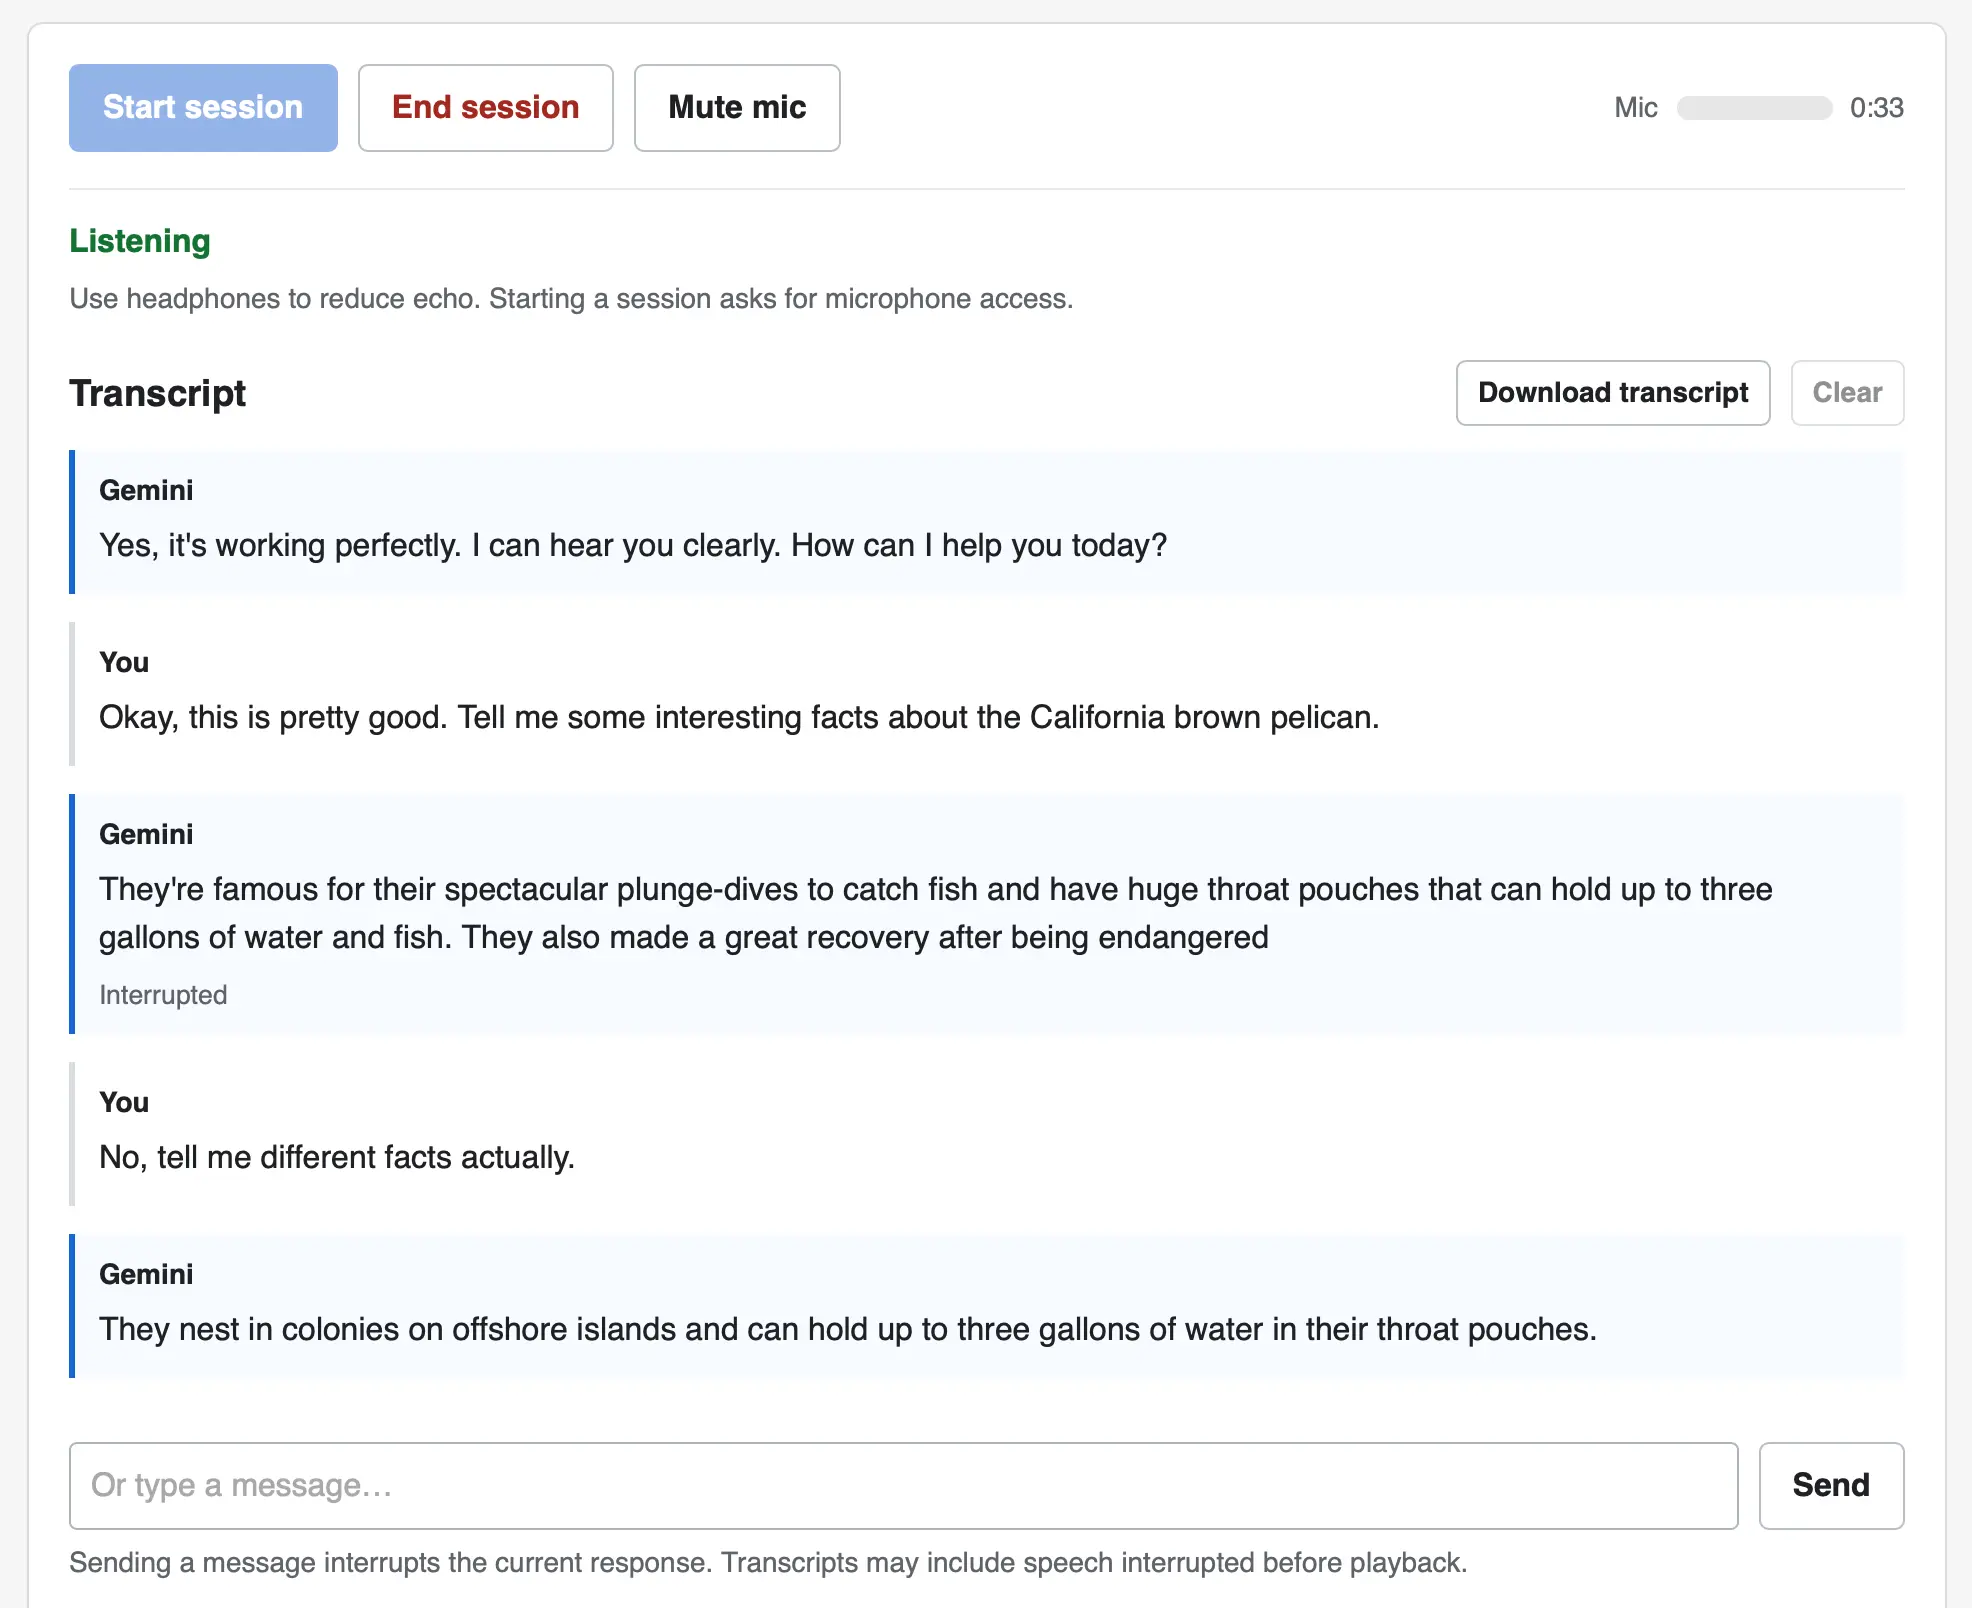
Simon Willison shows a minimal JavaScript UI that talks to Google’s Gemini 3.8 Live speech‑to‑speech models via a WebSocket API, using the Web Audio API for capture/playback and no external libraries.

  • Google’s Gemini 3.8 Live and Live Extended Thinking expose a bidirectional WebSocket endpoint for real‑time speech‑to‑speech.
  • A tiny HTML/JS client can stream microphone audio, send it to the model, and play back the model’s audio response using the Web Audio API.
  • The implementation (gemini‑live.html) is library‑free and demonstrates how to select model, voice preset, and optional system prompt, plus interrupt the model mid‑utterance.

Provides a concrete, low‑dependency example for building real‑time LLM‑driven voice assistants in the browser, useful for engineers exploring AI‑augmented UI or prototyping speech interfaces without heavy SDKs.

5/10
Related reading

  1. Gemini 3.8 Live models now available on AI Gateway

    Vercel AI Gateway now offers Google’s Gemini 3.8 Live and Live Extended Thinking models through its realtime WebSocket API, enabling real‑time spoken interactions with audio output and parallel reasoning. The post includes a short TypeScript example for token acquisition, WebSocket setup, and handling of realtime events.

    Vercelvercel.com1 minrelease
  2. GPT-Live 1 now available on AI Gateway

    Vercel AI Gateway now offers OpenAI’s GPT‑Live 1, a full‑duplex voice model that can listen and speak simultaneously. The SDK lets you start a voice session and optionally delegate work to any text model, with code examples for both patterns.

    Vercelvercel.com1 minrelease
  3. Agent Anomaly Detection, now in Private Preview on the Gemini Enterprise Agent Platform

    Google’s Gemini Enterprise Agent Platform now offers a private‑preview Agent Anomaly Detection service that asynchronously analyzes agents’ OpenTelemetry traces and logs to flag risky behavior (e.g., tool misuse, privilege abuse) without adding latency, surfacing findings in Security Command Center and via an API for automated mitigation.

    Google Developersgoogleblog.com4 min
  4. StepAudio 3 Realtime Technical Report

    StepAudio 3 Realtime is an audio‑language foundation model that runs a continuous listen‑converse‑think‑act loop. It introduces Deep Perception for rich acoustic cue extraction, Seamless Duplex for handling pauses/back‑channels, and a Think‑While‑Speaking mechanism that lets the model reason in parallel with speech output. On benchmarks it scores 73.0 macro avg on StepAudioChat, 90.6 on MMSU, 98.…

    Hugging Face Daily Papersarxiv.org2 minpaper
  5. llm-keys-ui 0.1

    Simon Willison released llm-keys-ui 0.1, a tiny web UI that lets you store LLM API keys on a remote machine and retrieve them via the llm CLI, avoiding pasting keys into chat sessions. It runs with a single uvx command and exposes local network URLs for access.

    Simon Willisonsimonwillison.net1 minrelease