proomt

Search

Search posts, papers, and topics

All posts

Hacker News front page1 min readrelease notesintro

Alibaba releases Qwen 3.8 Omni Flash

Summary

Alibaba announced the release of Qwen 3.8 Omni Flash, a new model in their Qwen series. The article provided no specific technical details, features, or performance metrics regarding this release.

  • Alibaba has released a new model named Qwen 3.8 Omni Flash.
  • This is an addition to their existing Qwen model series.

This release signals continued development in the LLM space by a major player, which could impact future AI applications and research.

3/10
Related reading

  1. Qwen 3.8 Max now available on Vercel AI Gateway

    Vercel AI Gateway now offers Qwen 3.8 Max, a 2.4 T‑parameter multimodal LLM with up to 1 M token context. It can be invoked via the standard `streamText` API or through Vercel’s coding agents, with no extra platform fees and full control over usage and security.

    Vercelvercel.com1 minrelease
  2. Shapelearn Qwen 3.8 27B (13.1 GB VRAM)

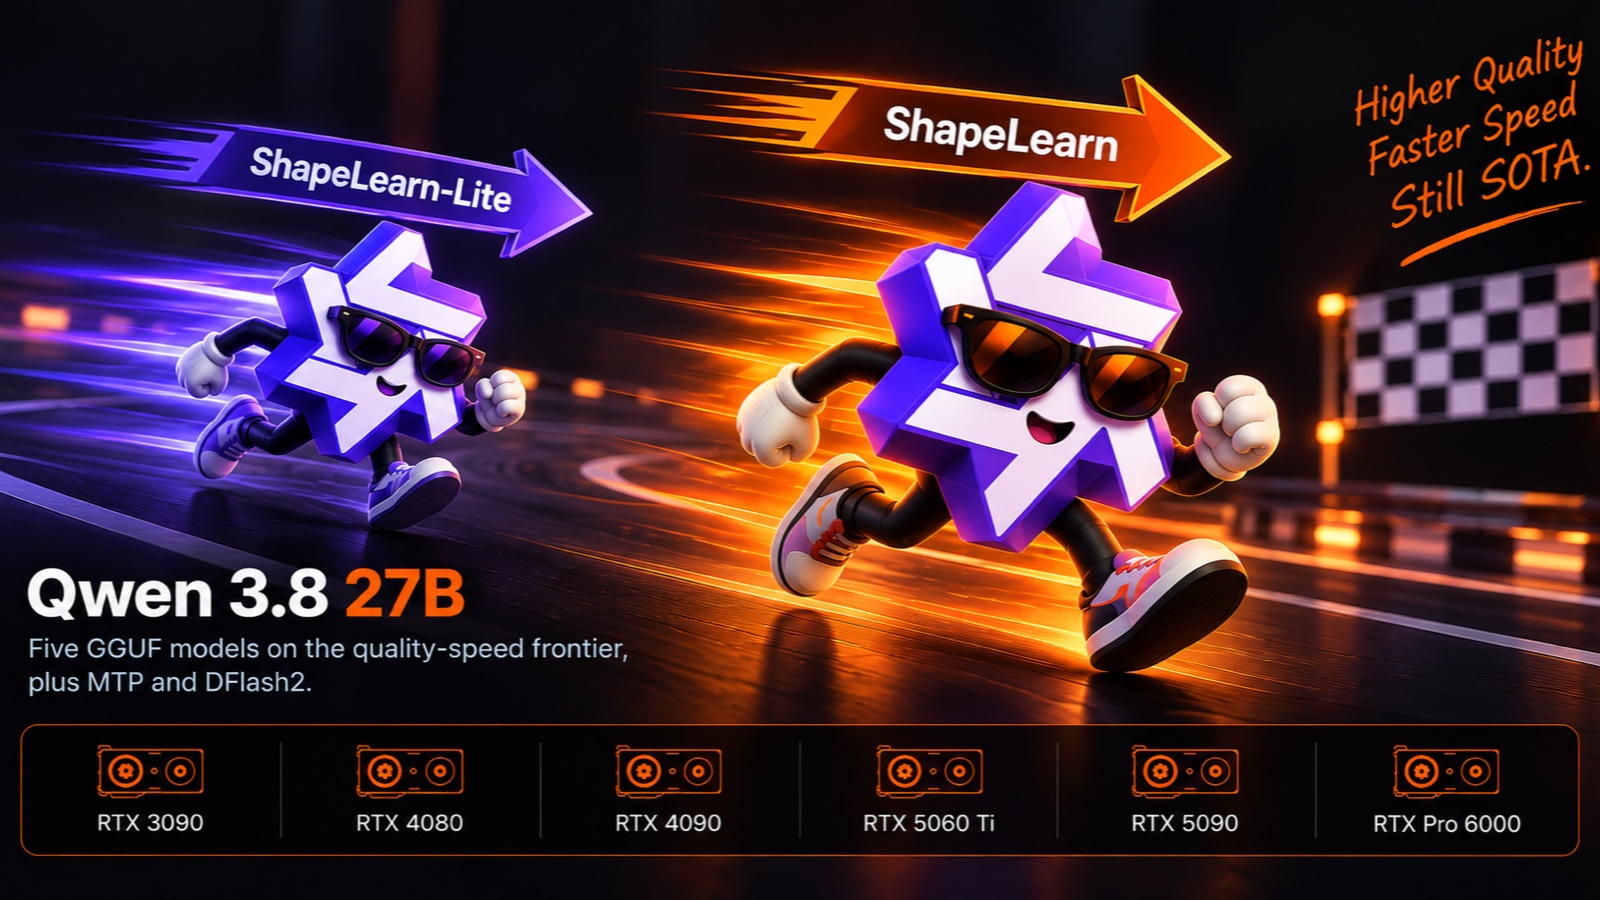
    ByteShape releases full ShapeLearn quantizations for Qwen 3.8 27B, showing that their GPU‑specific GGUFs (GPU‑1…GPU‑5) dominate the quality‑throughput frontier across six GPUs, with GPU‑5 hitting 99.63 % of BF16 accuracy at 90 TPS on a 13.1 GB model. Speculative decoding (MTP, DFlash2) further boosts throughput, and the Lite set remains competitive.

    Hacker News front pagebyteshape.com17 minHN10439
  3. Alibaba Open Sources OpenCodeReview for AI-Assisted Code Review

    Alibaba open-sourced OpenCodeReview, an AI-powered code review CLI that combines deterministic pipelines for file selection and rule matching with an LLM agent for dynamic analysis. Used internally for two years, it claims higher precision and F1 scores than Claude Code with fewer tokens, though external reviews note recall limitations.

    InfoQinfoq.com2 min
  4. M5 Ultra Mac Studio Review

    The M5 Ultra Mac Studio (256 GB RAM) uses a quad‑die M5 Max architecture with an 80‑core GPU and 1.2 TB/s memory bandwidth, delivering ~70 % faster prompt‑to‑first‑token and token‑generation rates than the M3 Ultra. In the author’s tests Qwen3.8‑Flash‑Next hits 100 tokens/s on short prompts and 60‑85 tokens/s with 64‑256 KB context, making local AI agents (Open Minis, Hermes, Codex) feel snappy a…

    Hacker News front pagemacstories.net39 minHN234235