Related reading
LensVLM-9B by Apple
Hacker News front pagehuggingface.coHN241ModaLens: Measuring Image Sensitivity in Report-Conditioned Medical VLMs
ModaLens introduces a paired image-swap audit to measure how radiology report availability affects image sensitivity in medical VLMs. It found that MedGemma-27B's answers changed significantly more often when the image was swapped if the report was not available, indicating reports reduce image reliance.
Hugging Face Daily Papersarxiv.org1 minpaperHyperBrowseComp: A Multilingual and Multimodal Stress Test for Web-Browsing Agents
HyperBrowseComp is a new multilingual and multimodal benchmark for web-browsing AI agents, featuring 423 challenging, human-validated questions across 13 languages. It requires agents to find obscure evidence and connect information from diverse sources like videos and maps, going beyond parametric knowledge.
Hugging Face Daily Papersarxiv.org1 minpaperThe Reflexes Machine turns a reaction game into an interactive experience
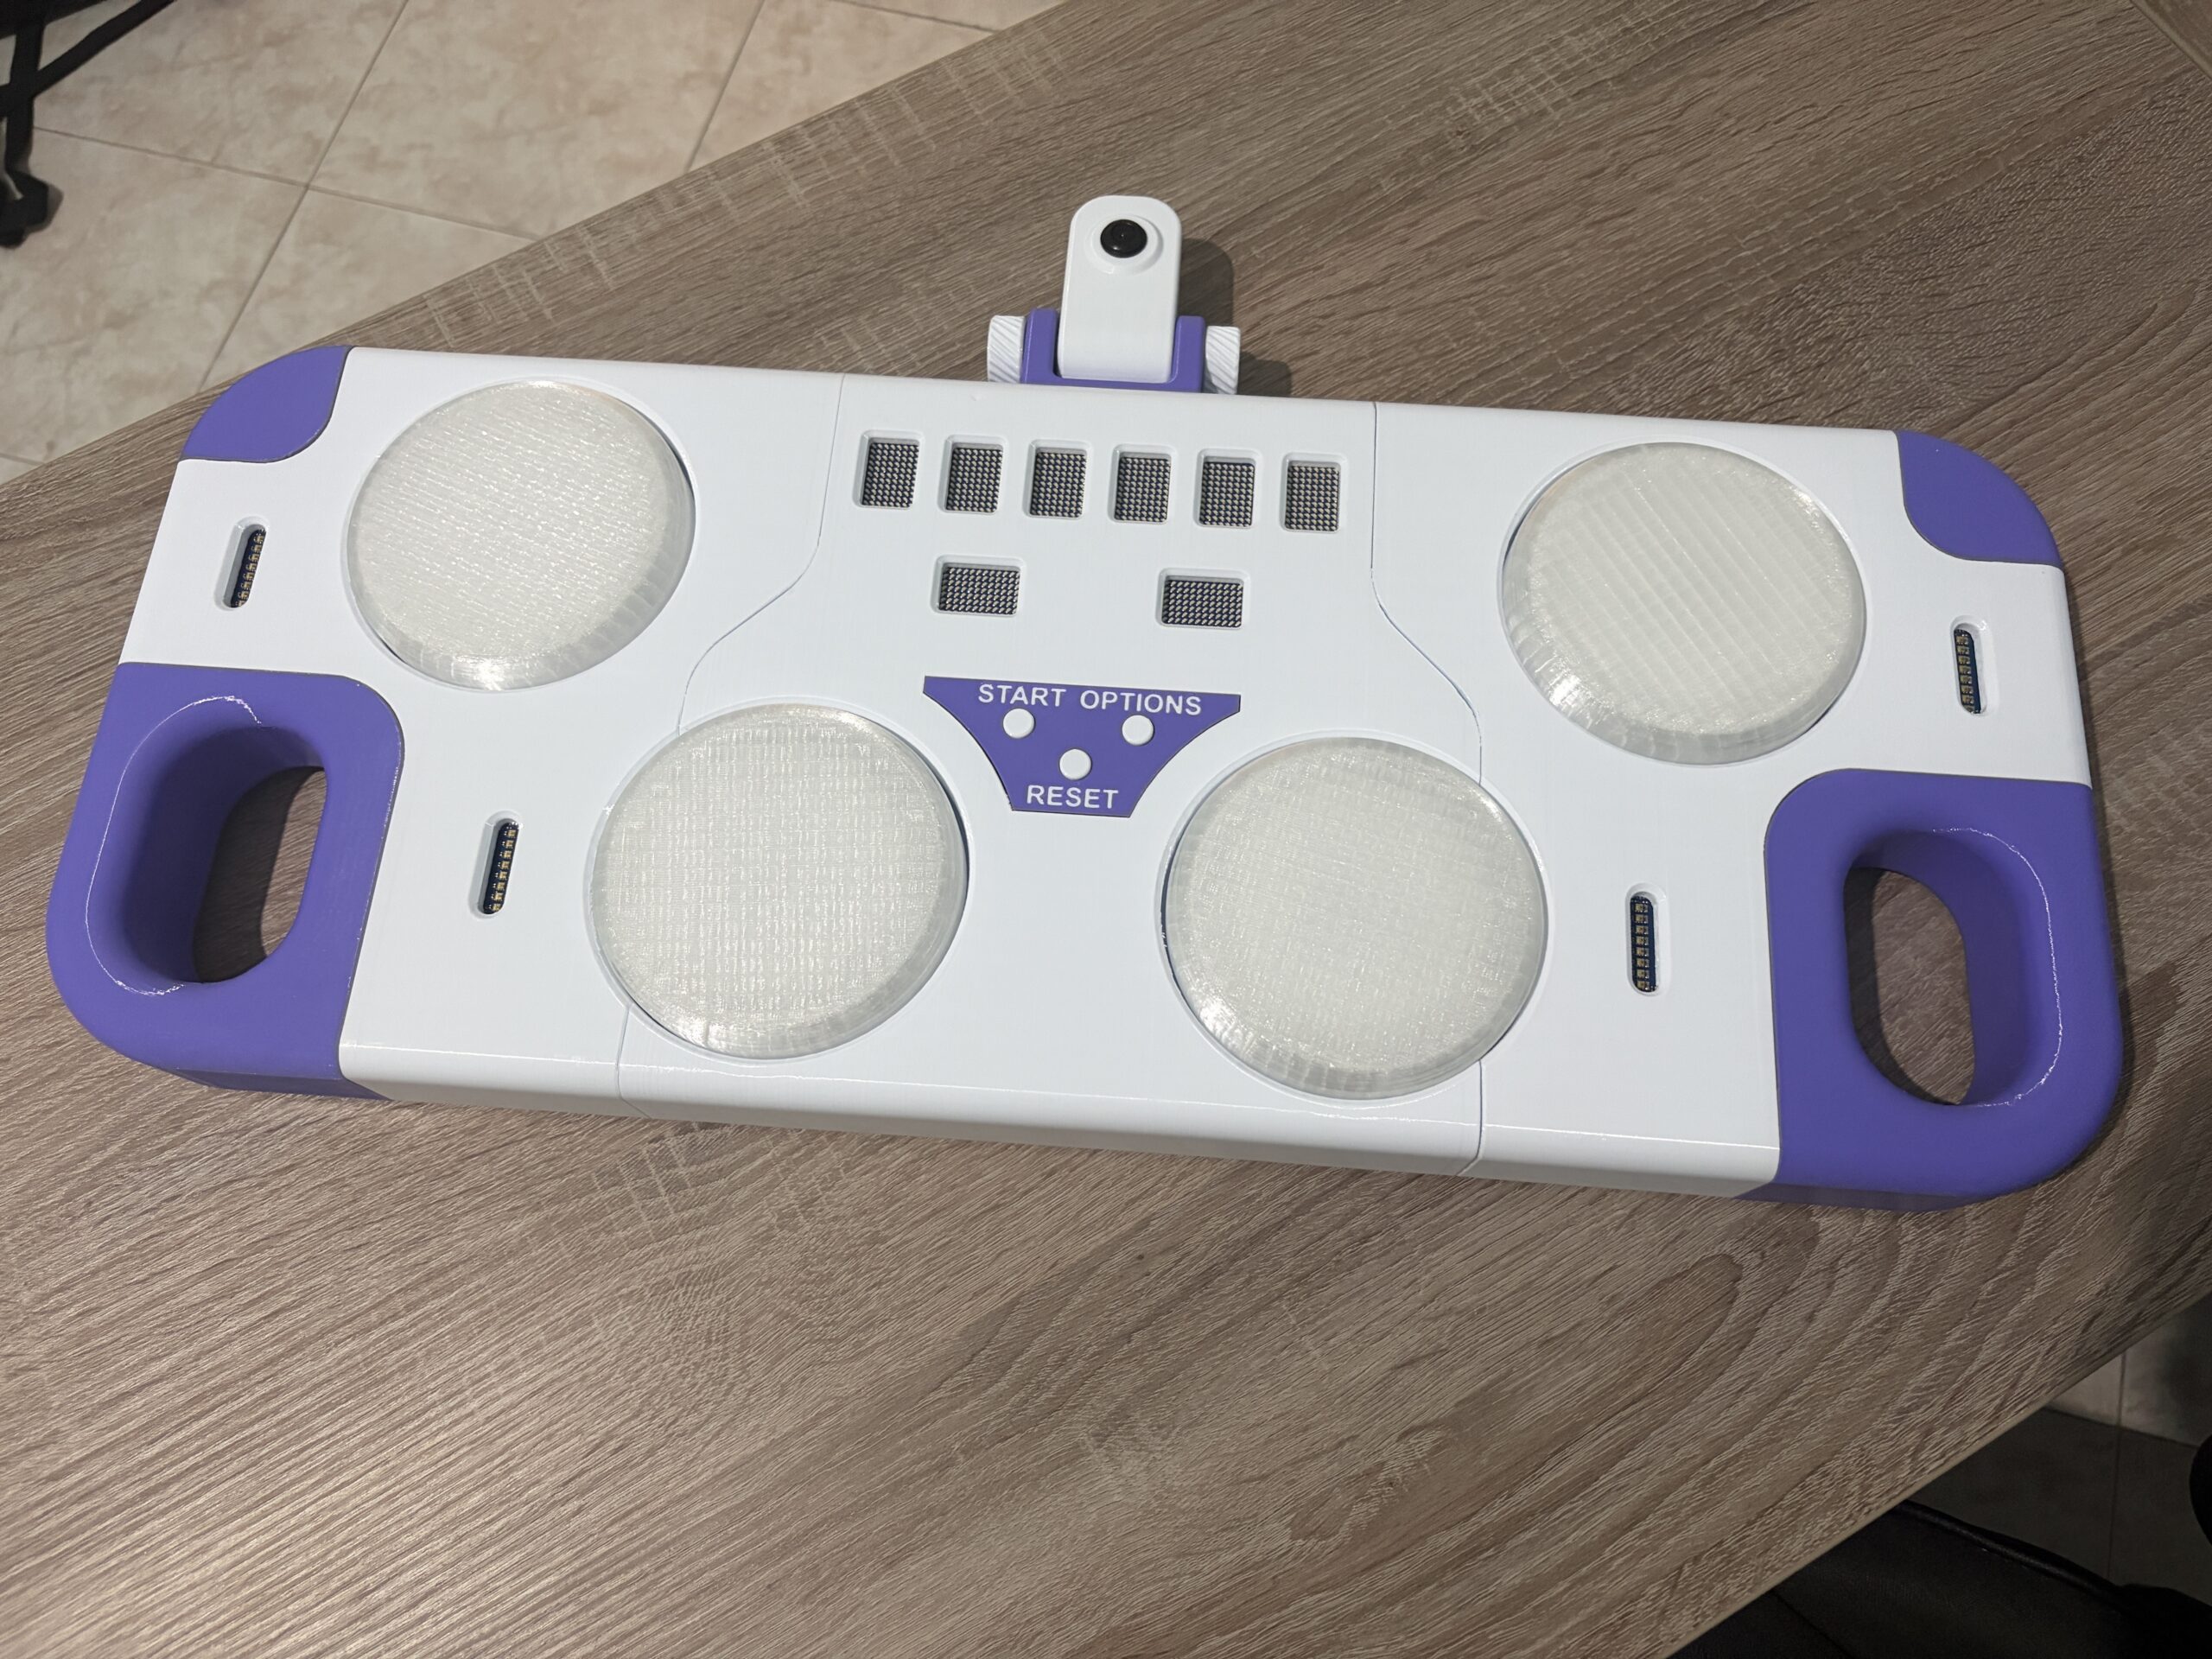
The article showcases a reaction‑game project built on an Arduino UNO Q that uses its dual‑brain (Linux + real‑time MCU) to run face‑detection via a USB camera and drive 12 Modulino I²C modules (LED matrices, pixels, thermo) plus arcade buttons and sound. It emphasizes the ease of wiring modular blocks together but offers no code, performance data, or deeper design discussion.
Arduino Blogarduino.cc2 minArticle: Architecting Secure and Scalable Facial Verification Systems
A real‑world post‑mortem of a high‑volume face verification service that moved from a naïve synchronous API to an async, layered pipeline (edge validation, preprocessing, decoupled detection/verification, decision engine) to achieve 8.5k rpm, p99 < 1.8 s, 30 % cost savings, and strict privacy controls.
InfoQinfoq.com15 minAnswerMap: Faithful Spatial Interpretability of VLMs from Answer Posteriors
AnswerMap is a novel, training-free, black-box method for generating faithful spatial interpretability maps for Vision-Language Models (VLMs) directly from their output posteriors. It queries the VLM with image bands and yes/no relevance questions, demonstrating higher faithfulness than attention maps and enabling new applications like object localization and hallucination detection.
Hugging Face Daily Papersarxiv.org1 minpaper