proomt

Search

Search posts, papers, and topics

All posts

Hugging Face Daily PapersRuixiang Zhao, Hualei Wang, Renhe Sun1 min readpaperintermediate

Realtime-Venus: A full-duplex interaction system with asynchronous delegation

Summary

Realtime-Venus is a full‑duplex, multimodal dialogue system built from two separately trained 9B models (Omni for audio‑visual, Audio for spoken interaction). It uses a shared causal timeline and a dual‑loop runtime that lets foreground interaction continue while a background Harness executes delegated tasks asynchronously. The paper reports benchmark scores where Realtime‑Venus‑Omni leads on six…

  • Two 9B LLMs are trained for distinct modalities but share a unified post‑training recipe (offline understanding + proactive full‑duplex trajectories + delegation workflow).
  • A dual‑loop runtime separates foreground interaction from background reasoning, enabling asynchronous tool execution without breaking the dialogue flow.
  • Benchmark results show state‑of‑the‑art performance on both video and audio tasks, and strong interruption‑handling metrics (75% response to user interruptions, continuation rates up to 97%).

Real‑time multimodal agents need to handle continuous perception, user interruptions, and background tool use without latency spikes. Realtime‑Venus demonstrates a practical architecture that achieves this with large models, offering a reference for building production‑grade, full‑duplex AI assista…

6/10
Related reading

  1. OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

    OmniVChat defines native audio‑visual dialogue where a model consumes raw audio and video streams and replies in text. The authors build OmniVChat‑Studio, a multi‑agent simulator that generates single‑ and multi‑turn audio‑visual conversations, and use it to create OmniVChat‑Bench, a benchmark covering five dialogue abilities. They also propose OmniVChat‑RL, a reinforcement‑learning reward that b…

    Hugging Face Daily Papersarxiv.org2 minpaper
  2. SteerDuplex: Steerable Duplex Speech Dialogue Models

    The paper presents SteerDuplex, a full‑duplex speech dialogue model that can be steered along tone, persona, and speed via instruction following, and introduces the SteerBench benchmark to evaluate such steerability. Supervised training yields a 44.5 % pass‑rate lift, and reinforcement‑learning fine‑tuning improves interruption handling and reduces pause barge‑ins, though reward hacking remains a…

    Hugging Face Daily Papersarxiv.org2 minpaper
  3. How OpenAI Built GPT-Live

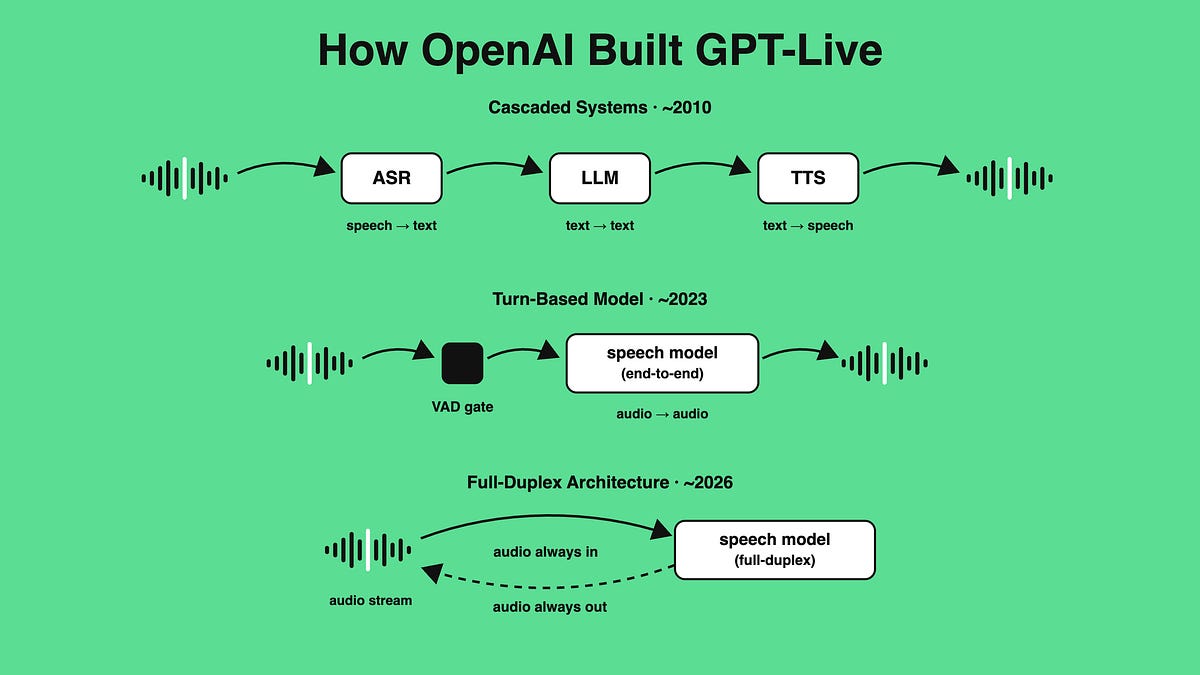
    OpenAI’s GPT‑Live‑1 is a full‑duplex voice model that can listen and speak simultaneously by tokenizing audio (including silence) and emitting tokens on an ~80 ms clock. By keeping the model small and fast and delegating heavy reasoning to a separate LLM, OpenAI solves the turn‑detector problem of earlier cascaded and turn‑based systems while meeting sub‑100 ms latency requirements. The post walk…

    ByteByteGobytebytego.com14 min
  4. StepAudio 3 Realtime Technical Report

    StepAudio 3 Realtime is an audio‑language foundation model that runs a continuous listen‑converse‑think‑act loop. It introduces Deep Perception for rich acoustic cue extraction, Seamless Duplex for handling pauses/back‑channels, and a Think‑While‑Speaking mechanism that lets the model reason in parallel with speech output. On benchmarks it scores 73.0 macro avg on StepAudioChat, 90.6 on MMSU, 98.…

    Hugging Face Daily Papersarxiv.org2 minpaper
  5. Zing-0.5: Toward Playable Worlds with Real-Time Joint Action and Text Control

    Zing‑0.5 is a 5 B autoregressive world model that lets users control generated environments in real time using both keyboard actions and text prompts. The paper introduces unified action‑text conditioning, segment‑level teacher distillation, and a low‑cost streaming inference pipeline that runs at 24 FPS (832×480) for about $0.009 per minute, achieving 81 % overall and 88.5 % consistency on a nav…

    Hugging Face Daily Papersarxiv.org1 minpaper