proomt

Search

Search posts, papers, and topics

All posts

Hugging Face Daily PapersYanjie Zhang, Nanchen Hu, Yushi Sun1 min readpaperadvanced

Do Audio LLMs Listen Before They Act? Diagnosing Acoustic-Context Gating in Voice Agents

Summary

The authors present VGBench, a 1,018‑item diagnostic suite that tests whether audio LLMs correctly mute actions when the acoustic context shifts (e.g., speaker switches). Training with VoxGate dramatically improves gating, raising mute rates from <15% to >90% while preserving tool‑call accuracy.

  • VGBench isolates action‑level addressedness across side‑talk, self‑talk, and speaker‑switch scenarios with controlled acoustic variables.
  • Six raw Audio LLMs rarely mute under speaker‑switch conditions, achieving at most a 14% mute rate.
  • Supervised fine‑tuning (VoxGate) raises mute rates to 91.3% on switched commands without harming tool‑call performance on wearer speech.
  • Factorized controls reveal that source‑change alone drives muting, while far‑field rendering effects vary by model.

Voice‑assistant developers need reliable gating to avoid unintended actions; this benchmark and training recipe provide a concrete way to evaluate and improve that behavior.

7/10
Related reading

  1. How OpenAI Built GPT-Live

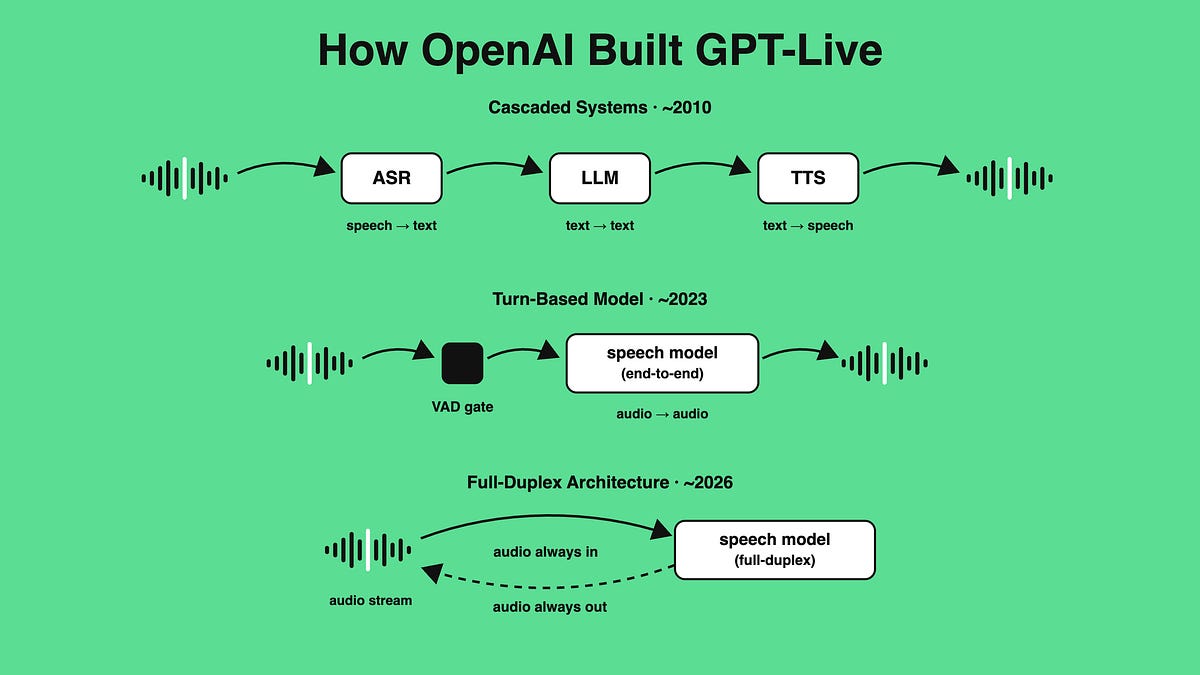
    OpenAI’s GPT‑Live‑1 is a full‑duplex voice model that can listen and speak simultaneously by tokenizing audio (including silence) and emitting tokens on an ~80 ms clock. By keeping the model small and fast and delegating heavy reasoning to a separate LLM, OpenAI solves the turn‑detector problem of earlier cascaded and turn‑based systems while meeting sub‑100 ms latency requirements. The post walk…

    ByteByteGobytebytego.com14 min
  2. OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

    OmniVChat defines native audio‑visual dialogue where a model consumes raw audio and video streams and replies in text. The authors build OmniVChat‑Studio, a multi‑agent simulator that generates single‑ and multi‑turn audio‑visual conversations, and use it to create OmniVChat‑Bench, a benchmark covering five dialogue abilities. They also propose OmniVChat‑RL, a reinforcement‑learning reward that b…

    Hugging Face Daily Papersarxiv.org2 minpaper
  3. FRAUDSkill: Structured Frozen-Weight Skill Optimization for Audio Anti-Fraud Detection

    FRAUDSkill is a framework that keeps a pretrained audio‑language model frozen and learns an external layer of skill programs, routing policies, and decision rules to meet a structured anti‑fraud detection protocol. On the TeleAntiFraud benchmark it reaches 73.5% Macro‑F1 (≈32% improvement) while cutting invalid predictions to 1.94%.

    Hugging Face Daily Papersarxiv.org1 minpaper