proomt

Search

Search posts, papers, and topics

All posts

Hugging Face Daily PapersZheyuan Zhang, Alvin Zhang, Daniel Khashabi1 min readpaperadvanced

Continual Learning Mechanisms Compose for Long-Horizon Memorization

Summary

The paper studies long‑horizon memorization where a language model must learn 100 tasks via continual fine‑tuning without retaining data or task IDs. By composing data, function, and weight anchors with merged LoRA, they boost final retention from 1.2% to 34.9%, a 28× improvement.

  • Naïve sequential fine‑tuning retains only ~1% of knowledge after 100 tasks due to catastrophic forgetting.
  • Composing data, function, and weight anchors with merged LoRA yields the best retention, achieving ~35% on average.
  • Task‑level successive halving efficiently searches the combinatorial space of mechanism compositions.
  • Factorial experiments reveal that data anchors and merged LoRA provide the largest gains and interact super‑additively.

Anyone deploying LLMs that must continuously ingest new information should care, as the proposed composition dramatically reduces forgetting compared to standard fine‑tuning.

8/10

Related reading

  1. Designer-RSI: Evolving Procedural Memory from User Traffic for Agentic Graphic Design

    The paper introduces Designer‑RSI, a continual‑adaptation system that couples a frozen design‑software‑controlling LLM with an external procedural memory of natural‑language design skills. Over five adaptation rounds on real user briefs, the memory grows from 76 to 139 procedures and lifts execution success from 72.7% to 99.3%, showing that skill accumulation and selective replay can dramatically…

    Hugging Face Daily Papersarxiv.org1 minpaper
  2. Do LLMs Have the Memory of a Goldfish?

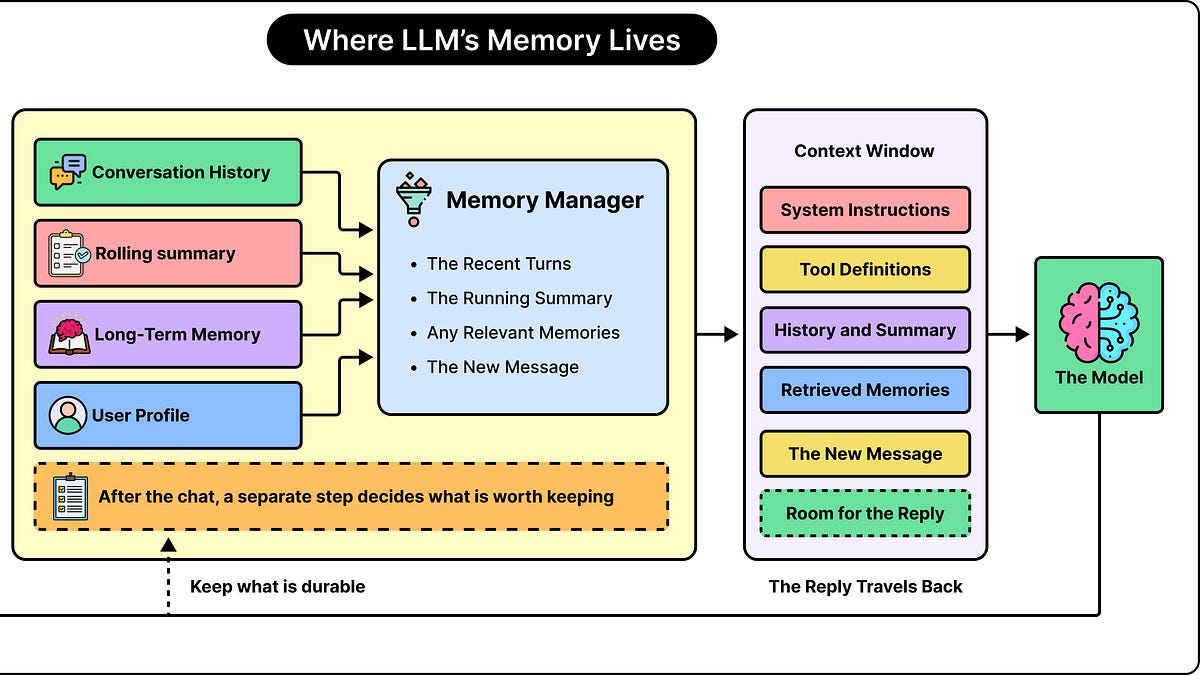
    The article explains that LLMs don’t have persistent personal memory; all “memory” is supplied by the surrounding application via the context window, summaries, or external storage. It outlines the distinction between trained weights, working‑memory (token context), and persistent application memory, shows how to construct API calls to preserve conversation state, and discusses the cost and laten…

    ByteByteGobytebytego.com12 min
  3. Learning to solve hard problems in RL for LLMs by never giving up

    The post introduces the *Matthew Effect* in RL‑fine‑tuning of LLMs—performance gains concentrate on tasks the model already solves— and proposes *Never Give Up* (NGU), an adaptive sampling scheme that uses a small k for easy prompts and retries hard prompts with a high‑probability “never give up” loop. Experiments on math (AIME, GSM8k), code (Manufactoria), and larger‑scale setups (DeepScaler) sh…

    Hacker News front pagegithub.io11 minHN1179
  4. Shared Selective Persistent Memory for Agentic LLM Systems

    Apple proposes a memory architecture for agentic LLMs that selectively persists reusable context (specs, schemas, configs, constraints) across sessions and users. Shared workspaces with role‑based access and a zero‑token data‑refresh mechanism cut token usage by 97×, reduce task time by 14×, and raise task‑completion rates to 96% versus 71%‑79% for baselines.

    Apple Machine Learning Researchapple.com1 minpaper
  5. The Router Within: Eliciting Native Skill Routing from a Frozen LLM

    The paper introduces Gavel, a method that extracts a frozen LLM's internal routing signal via two trained linear maps, eliminating the need to embed skill descriptions in the prompt. Experiments on Qwen3‑32B show up to 13.4‑point improvements on task benchmarks and higher skill‑use accuracy compared to larger retrieval‑based systems.

    Hugging Face Daily Papersarxiv.org1 minpaper
  6. Show HN: Mini-AGI – Dynamic continual learning model trained on 8GB VRAM

    mini-AGI is a byte‑level continual‑learning language model that fits on a single 8 GB GPU by paging expert weight files from disk. It uses two dense prelude blocks followed by a recurrent block applied up to 24 times per character, with adaptive depth (PonderNet halting) and per‑application top‑8 expert routing. The system maintains a RAM cache and a VRAM resident set, swaps experts based on dema…

    Hacker News front pagegithub.com20 minHN25657lobste.rs2