proomt

Search

Search posts, papers, and topics

All posts

Databricks9 min readintermediate

Database Branching: A Developer's Guide to Git-Style Workflows

Summary

Database branching uses copy‑on‑write to give developers, CI jobs, and AI agents isolated database snapshots without full copies. Branches share unchanged data, store only deltas, and are disposable, enabling production‑like testing, per‑PR isolation, safe experimentation, and rapid cleanup. Safe operation requires protecting parent branches, using mock data, TTLs, and treating migrations as the…

  • Copy‑on‑write lets a branch start with the parent’s data and only consumes storage for changed rows (e.g., a 40 GB DB can spawn two branches that add only ~5 MB of storage).
  • Branches are ideal for per‑pull‑request CI: create a branch, apply migrations, run integration tests, then delete it, avoiding interference between concurrent PRs.
  • Production‑like snapshots expose migration bugs that only appear on real data (e.g., adding a NOT NULL column to a table with millions of rows).
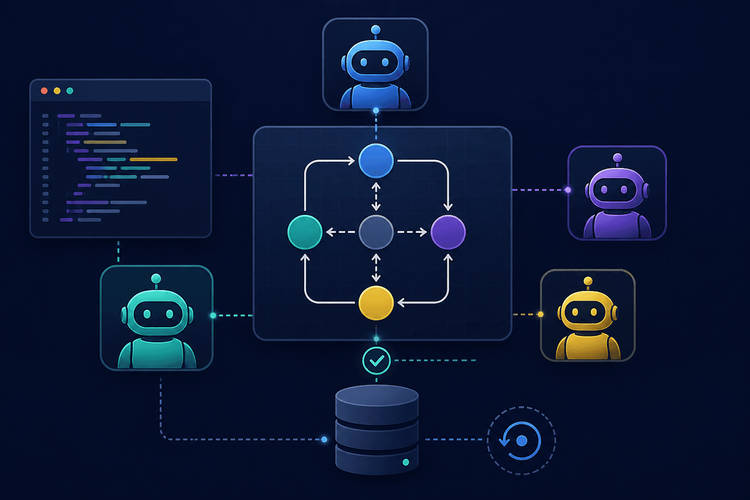
  • AI agents can spin up hundreds of short‑lived branches to test different strategies without risking the parent database.

Without branching, teams either share a mutable staging database—causing flaky tests and merge conflicts—or copy entire databases for each developer/CI run, which is costly and slow. Copy‑on‑write branching provides Git‑style isolation at scale, crucial for modern CI pipelines and for AI agents tha…

5/10

Related reading

  1. Database for AI Agents: 5 Evaluation Criteria

    Databricks outlines five criteria for a production‑ready database for AI agents—branch‑per‑agent isolation, serverless scale‑to‑zero, hybrid search, ACID guarantees, and a unified platform that eliminates ETL lag—illustrating each with features of its Lakebase offering and brief customer anecdotes.

    Databricksdatabricks.com10 min
  2. Reinventing issue tracking: Local-first and Git-native

    A devlog describing how Manganin’s issue tracker stores issues in a dedicated Git repo as plain files, after rejecting earlier approaches that tried to embed issue data in the code tree or Git refs. The author explains the pitfalls of using refs for issue storage, shows the low‑level Git commands needed for that approach, and then outlines the final design: a hidden sister repository where each i…

    Lobstersmanganin.dev6 minHN1lobste.rs27
  3. Blog: How to Build a DevOps Agent

    This blog walks through the open‑source DevOps Agent Kit, which lets Claude Code or Cursor act as a DevOps assistant by connecting to CloudBees Unify, Jira, and Slack via MCP servers and to GitHub via the CLI. It provides a repeatable setup (Docker, Node, env file) and seven slash commands for pipeline overview, triage, security, release readiness, flag management, CI health scoring, and Jira tic…

    Codeshipcloudbees.com10 min
  4. Building Deterministic Multi-Agent State Machines in TypeScript

    The article shows how to build a deterministic, checkpoint‑backed finite state machine engine in TypeScript for orchestrating multi‑agent AI workflows. It uses Zod for schema validation, better‑sqlite3 for atomic persistence, and a pure transition function to make workflows traceable and recoverable in serverless environments.

    SitePointsitepoint.com18 min