proomt

Search

Search posts, papers, and topics

All posts

Hacker News front pageSimon Klee42 min readadvanced
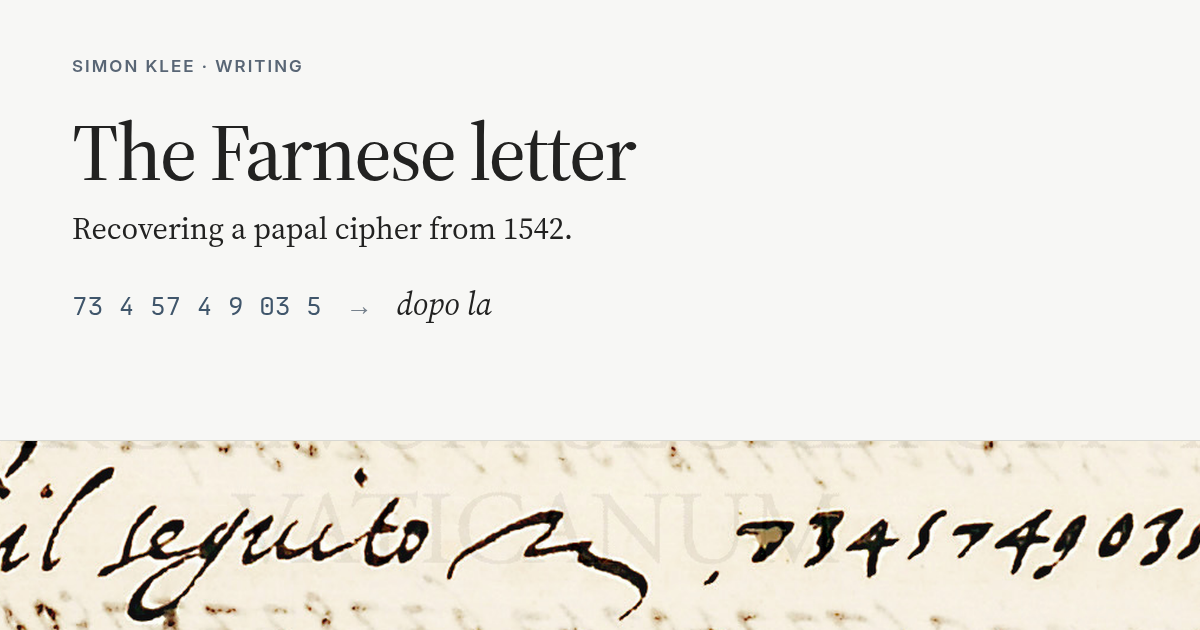
The Farnese letter

Summary

The author reverse‑engineers a 1542 Italian cipher from a Farnese letter by combining digit‑frequency analysis with a beam‑search decoder guided by a five‑gram Italian language model, ultimately recovering the key and partial plaintext.

  • A simulated‑annealing outer loop searches for letter‑to‑digit assignments while an inner beam search resolves ambiguous code boundaries.
  • Training a 5‑gram model on contemporary Italian texts (Machiavelli, Castiglione, etc.) provides a probabilistic scoring function for candidate decodings.
  • The recovered key maps 18 letters to one‑ or two‑digit codes, revealing phrases like “Dopo la partita del Montepulciano”.
  • Digit‑pair statistics (e.g., frequent pairs 80, 57) and the avoidance of doubles guided the design of the search space.

Historians and cryptographers can apply this data‑driven approach to other unsolved early modern ciphers.

8/10

Related reading

  1. Article: Your Next DSL Author Is a Language Model

    Typed Domain Grounding (TDG) embeds a DSL inside a mainstream language the LLM already knows (e.g., Kotlin) and uses the host compiler as an oracle. The author describes five building blocks—embedding, choosing a host language with high training‑data frequency, compiler‑driven type safety, a generate‑compile‑repair loop, and an on‑demand teaching tool—and shows measured results from kUML, a Kotli…

    InfoQinfoq.com18 min
  2. Fathom: Per-Query Read Depth for Sparse Decoding over Offloaded KV Caches

    Fathom introduces a per-query read depth mechanism for sparse decoding over offloaded KV caches, allowing each query to adaptively decide how many bits of each key channel to read. This method significantly speeds up decoding for large language models with long contexts by reducing host memory traffic, achieving 1.67x faster GPU decoding on Qwen3-8B at one million tokens.

    Hugging Face Daily Papersarxiv.org1 minpaper
  3. How Lossless Is Lossless Speculative Decoding? The Role of Numerical Precision in Orthrus

    This paper investigates the "lossless" claim of Orthrus, a hybrid architecture for accelerating LLM inference. It finds that under BF16 precision, Orthrus diverges from the exact autoregressive output trajectory in over 50% of cases, though FP32 maintains exact matching. Despite BF16 divergence, downstream task performance was not systematically degraded.

    Hugging Face Daily Papersarxiv.org1 minpaper
  4. Poisoned Documents, Real Risks: Sebastián Passaro Puts AI’s Weakest Link to the Test at Testear.la 2026

    Sebastián Passaro (Qubika) demonstrated a live RAG pipeline attack at Testear.la 2026, showing how a single poisoned document can hijack LLM outputs and trigger unsafe actions. He tied the demo to the OWASP LLM Top 10, highlighted open‑source tooling for finding such weaknesses, and advocated a defense‑in‑depth threat model for QA teams. The talk reframed AI from a testing aid to a security surfa…

    Moove-itqubika.com4 min