proomt

Search

Search posts, papers, and topics

All posts

Hugging Face Daily PapersBinxu Li, Haoyi Duan, Yuhui Zhang1 min readpaperadvanced

VideoGen-Agent: Reinforcing Video Generation Agents

Summary

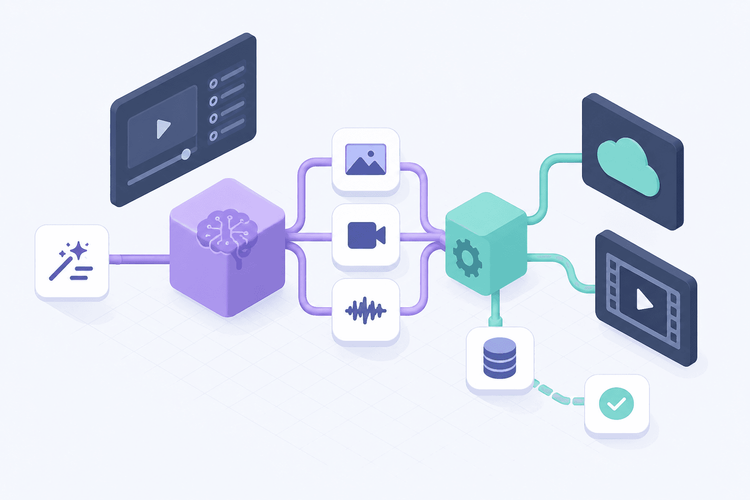
VideoGen-Agent is a multimodal RL‑trained agent that orchestrates augmentation, generation, and verification tools to improve text‑to‑video synthesis on a new 600‑prompt benchmark (VABench). It lifts a base generator’s score from 56.5 to 75.6 (‑19.1 pts) and to 86.1 when the generation tools are upgraded, with 84.3% human preference over the strongest baseline.

  • Agentic RL can learn to select and sequence external video‑generation tools based on prompt semantics and intermediate observations.
  • A single shared policy, fine‑tuned on teacher‑generated trajectories, generalizes across six distinct video‑generation tasks (procedural knowledge, identity preservation, physics, composition, temporal structure).
  • The authors introduce VABench, a balanced 600‑prompt benchmark covering those tasks, enabling quantitative comparison of tool‑use agents versus standalone generators.
  • Hybrid, category‑aware reward combines tool‑call validity, task‑appropriate tool usage, and video quality metrics, driving measurable gains.

Current text‑to‑video models still fail on prompts that need domain knowledge, consistent identities, or ordered events. By treating video synthesis as a tool‑use problem, VideoGen‑Agent demonstrates a path to plug‑in better modules (e.g., higher‑fidelity generators) without re‑training the whole s…

8/10

Related reading

  1. Agent Substrate brings high-density, scalable, trusted infrastructure to GKE

    Agent Substrate is an open‑source runtime for AI agents that runs on GKE. It uses Cloud Hypervisor microVMs or gVisor sandboxes to give kernel‑level isolation, a custom control‑ and data‑plane that can suspend/resume agents in <500 ms, and a “zero‑idle” model that packs >1 000 dormant agents per host (≈10× density vs. containers). GKE integration adds custom ComputeClasses, spot/on‑demand pools,…

    Google Cloud Bloggoogle.com6 min
  2. VABench: Measuring Embodied Spatial Intelligence through Visual Demonstrations, Active Perception, and Metric Control

    VA‑Bench is a new benchmark that evaluates general‑purpose multimodal LLMs on the full observe‑reason‑act‑revise loop in embodied robotics, using RGB demonstrations, active camera control, and metric Cartesian commands. The best model reaches 53.9% average task success, showing active perception helps but long‑horizon tasks remain unsolved.

    Hugging Face Daily Papersarxiv.org1 minpaper
  3. OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

    OmniVChat defines native audio‑visual dialogue where a model consumes raw audio and video streams and replies in text. The authors build OmniVChat‑Studio, a multi‑agent simulator that generates single‑ and multi‑turn audio‑visual conversations, and use it to create OmniVChat‑Bench, a benchmark covering five dialogue abilities. They also propose OmniVChat‑RL, a reinforcement‑learning reward that b…

    Hugging Face Daily Papersarxiv.org2 minpaper
  4. OmniVBench: A Benchmark and Large-Scale Dataset for Omni Reference-to-Video Generation

    OmniVBench is a new benchmark and the Omni‑R2V Dataset, offering 7 task families, 18 fine‑grained reference‑to‑video generation tasks and a factor‑grounded evaluation checklist of over 12 k items. The dataset provides 340 k industrial‑grade video samples and pipelines for constructing reference‑target pairs, exposing large performance gaps in current R2V models.

    Hugging Face Daily Papersarxiv.org2 minpaper
  5. In-Context Robot Learning with VLM Agents

    GPT‑Policy is a framework that lets a large vision‑language model (e.g. GPT‑6 Astra) perform in‑context robot learning: a context compiler extracts visual transitions from demos, the VLM proposes tool actions, and a constrained controller verifies and executes them. Real‑robot experiments show that raw video demos improve success rates even without explicit action labels, and that providing align…

    Hugging Face Daily Papersarxiv.org1 minpaper