proomt

Search

Search posts, papers, and topics

Nvidia

12 posts · blogs.nvidia.com

  1. Why Deploying Physical AI at Scale Demands Safety at Every Layer

    NVIDIA’s Halos platform is a full‑stack safety system for physical AI (autonomous vehicles and industrial robots). It bundles safety‑engineered hardware (DRIVE AGX Thor, IGX Thor), an ASIL‑D certified OS (Halos OS), middleware for isolation and monitoring, AI models for explainability (Alpamayo), and simulation/validation tools (Isaac Lab, Omniverse). The blog argues that scaling physical AI requ…

    Nvidianvidia.com5 min
  2. AI Security Is an Engineering Problem — How to Solve It at Every Layer of the Agent Stack

    Nvidia frames AI security as an engineering discipline, outlining required controls across the AI agent stack (model, harness, runtime) and advocating for enforceable boundaries, traceable identities, and evidence‑based testing. It highlights OpenShell as a sandboxed runtime, the Open Secure AI Alliance, and several vendor tools for testing and red‑team exercises.

    Nvidianvidia.com4 min
  3. 5 Companies Using NVIDIA AI for Clean Energy

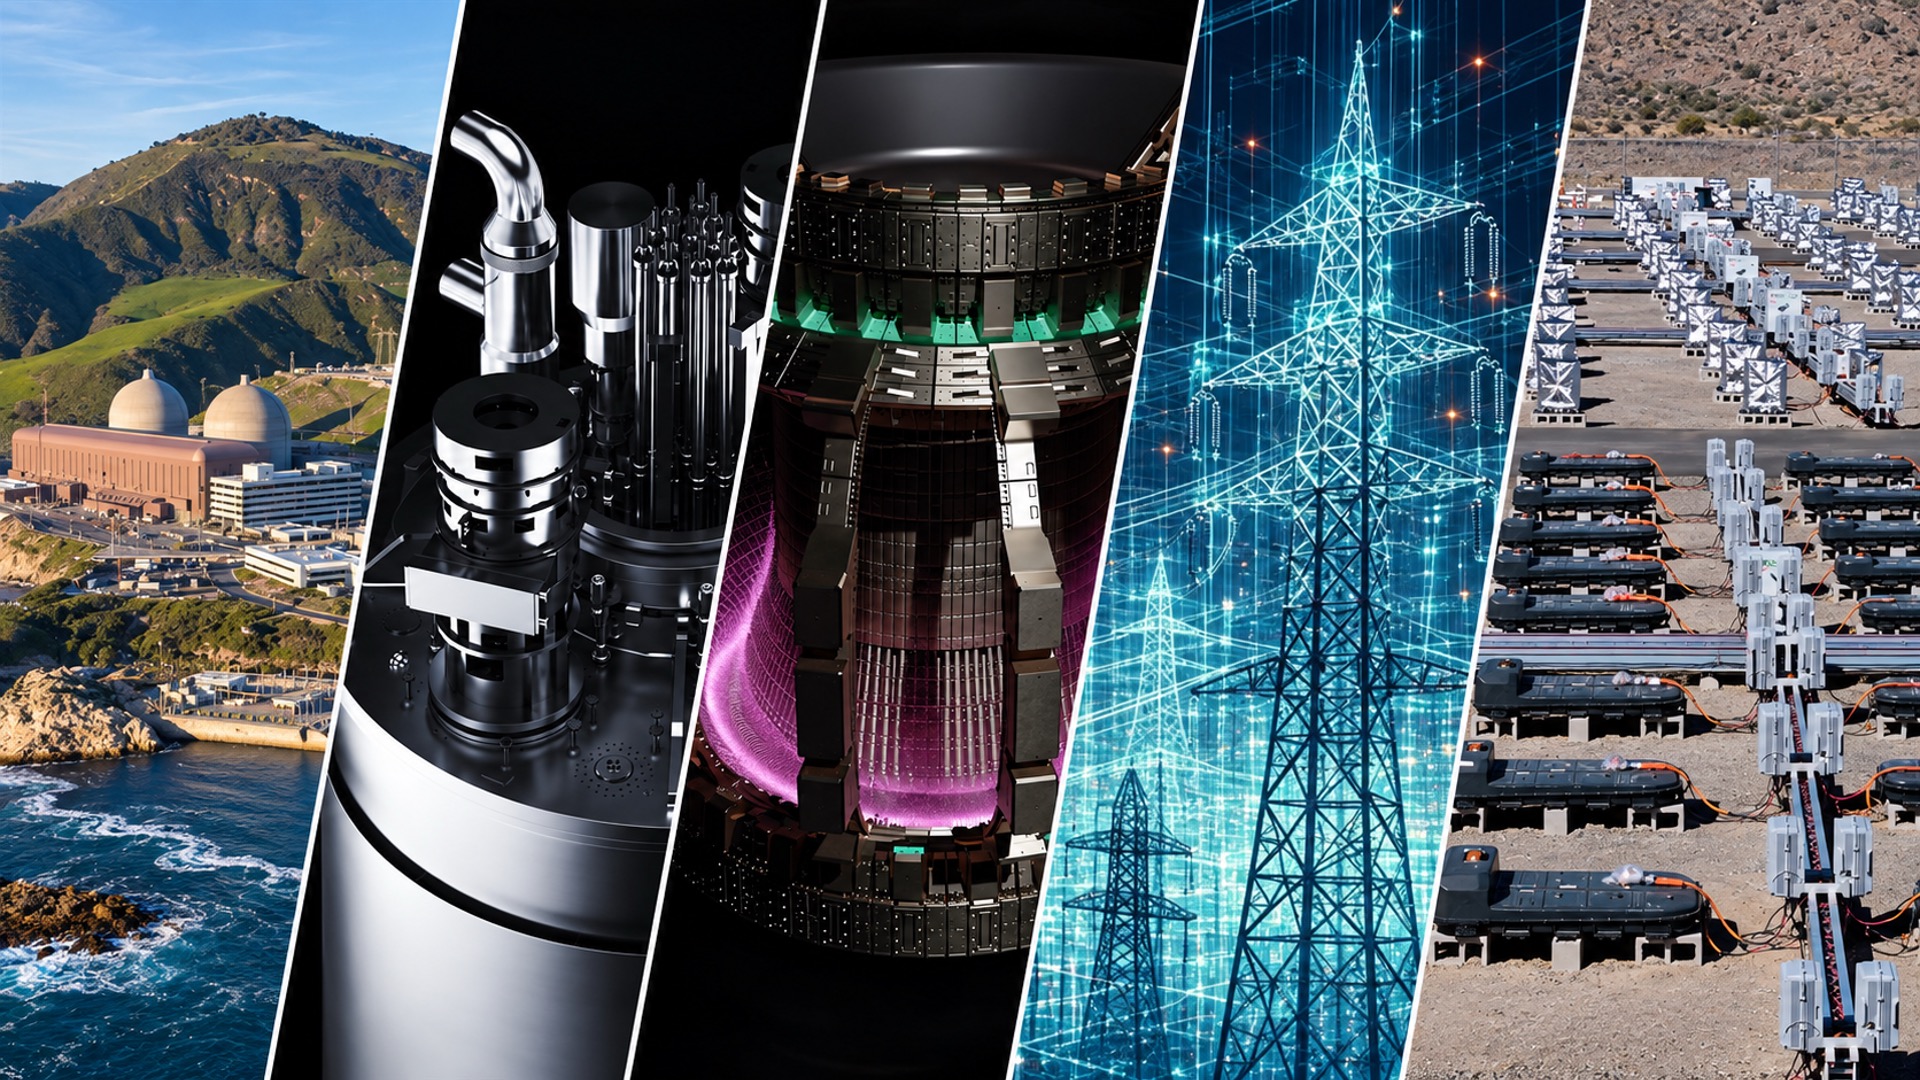
    Nvidia’s blog spotlights five companies that are using Nvidia AI platforms to accelerate clean‑energy projects—from grid interconnection and nuclear plant operations to off‑grid AI data‑center power, advanced reactors, and fusion tokamaks. The article is a marketing summary and provides few technical details.

    Nvidianvidia.com4 min
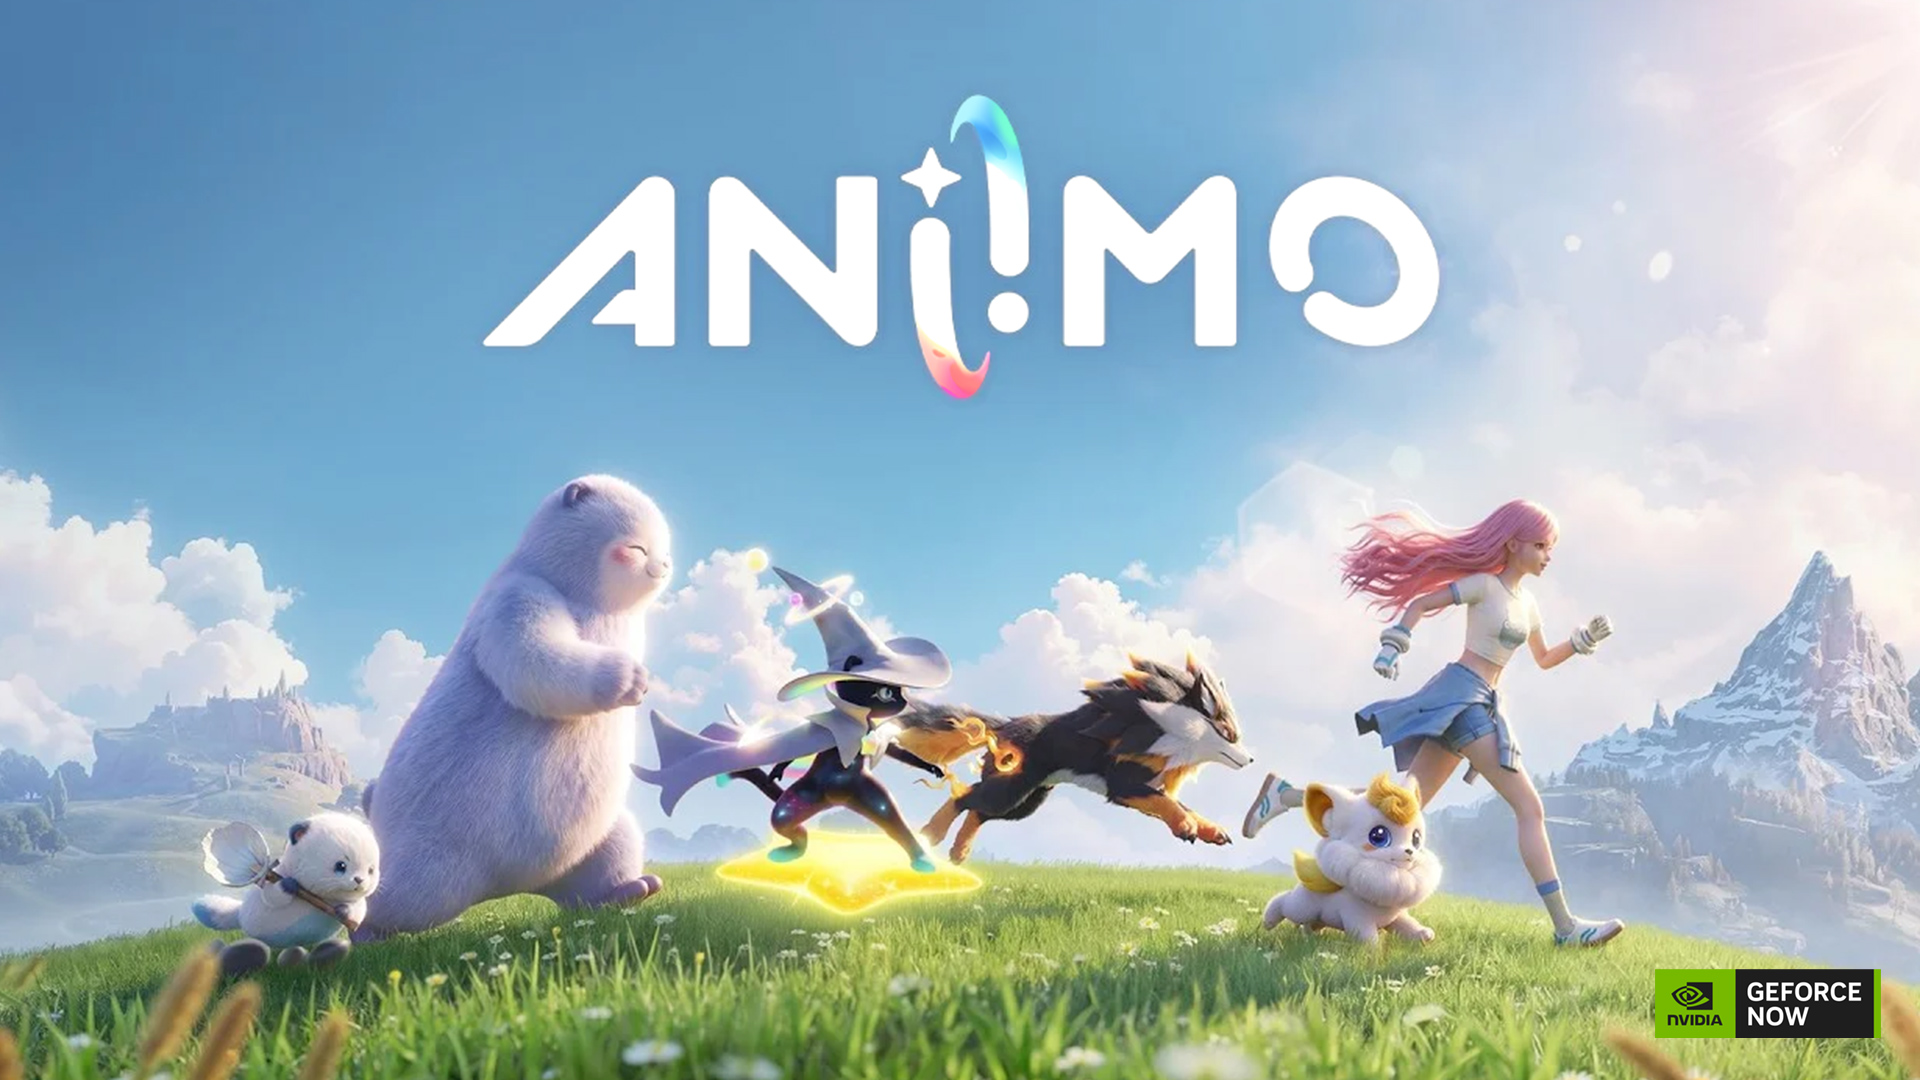
  4. Cute Critters Come to the Cloud: ‘Aniimo’ Launches on GeForce NOW

    Nvidia announced that the new creature‑catching game Aniimo and several other titles are now available on GeForce NOW, with features like path‑tracing for 007 First Light and RTX 5080‑class streaming for premium members. The update also lists 11 new games joining the service and notes a day‑pass that can be applied toward a monthly membership.

    Nvidianvidia.com3 min
  5. NVIDIA Vera Rubin NVL72 Delivers Leading Performance in MLPerf Inference v6.1 Debut

    NVIDIA’s Vera Rubin NVL72 AI inference system shows up to 3.7× higher throughput than the prior GB300 NVL72 on MLPerf v6.1 benchmarks (Qwen3‑VL, DeepSeek‑R1), achieves 99% scaling efficiency across 288 GPUs, and benefits from software optimizations (NVFP4 precision, kernel fusion, disaggregated serving). The post is a product announcement with concrete benchmark numbers but limited technical dept…

    Nvidianvidia.com4 min
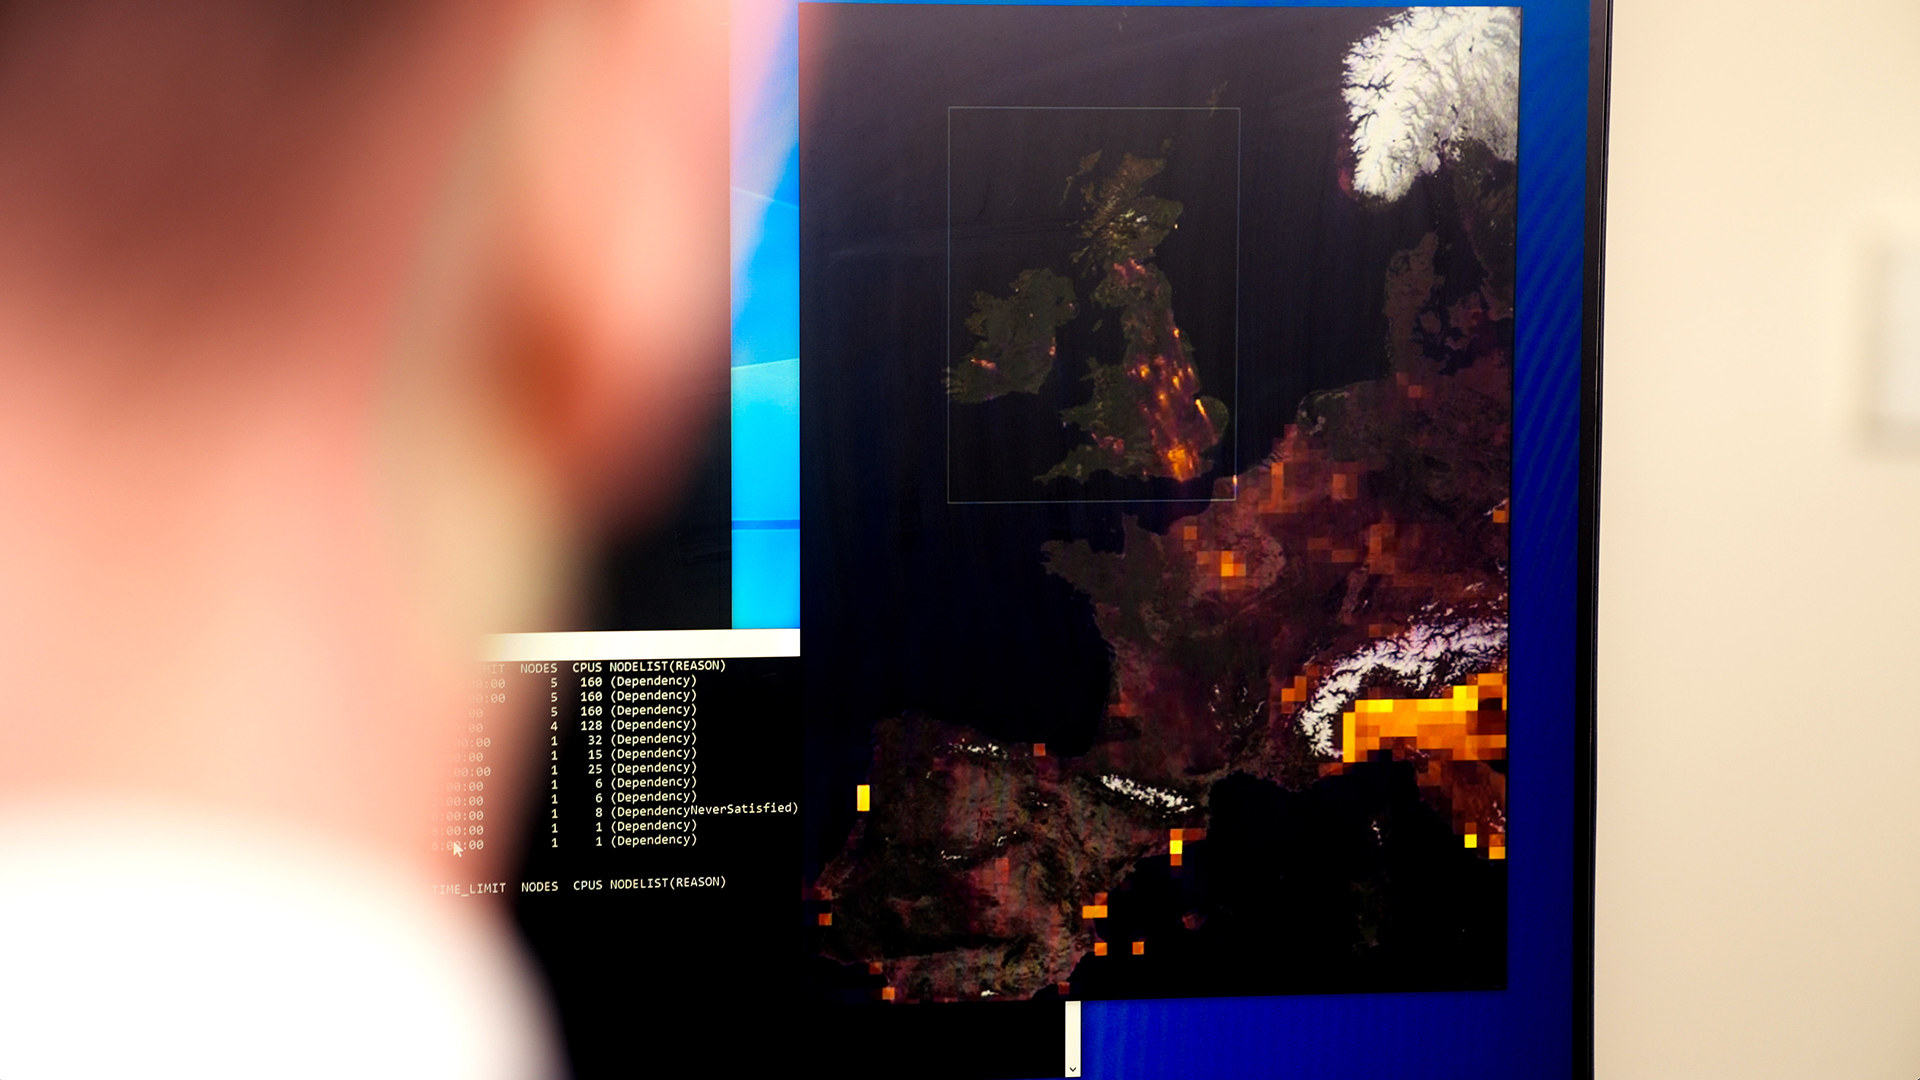
  6. University of Manchester Uses NVIDIA Earth-2 to Forecast Air Pollution Across the UK

    University of Manchester used NVIDIA Earth‑2 CorrDiff and StormCast generative models to downscale UK‑wide air‑pollution simulations. Training on the Isambard‑AI supercomputer (5,448 GH200 chips, 21 EFLOPS) took two days on an eight‑GPU node, producing a 2‑3 km resolution model. Inference runs on a desktop‑class DGX Spark, enabling rapid scenario forecasting and potential real‑time health alerts.…

    Nvidianvidia.com4 min
  7. ‘Now We Can Know Everything and Do Anything,’ Jensen Huang Says at Dreamforce

    Nvidia’s Jensen Huang announced Salesforce’s Koa, a CRM‑reasoning LLM built by fine‑tuning Nvidia Nemotron 3 Super on a synthetic, three‑decade‑spanning dataset. Koa uses supervised fine‑tuning plus RL (NeMo RL, Gym, AutoModel), covers 14+ industries, and claims 3× fewer errors on Salesforce’s CRM‑Bench versus leading models. It’s already in internal Slack agents and slated for limited customer p…

    Nvidianvidia.com3 min
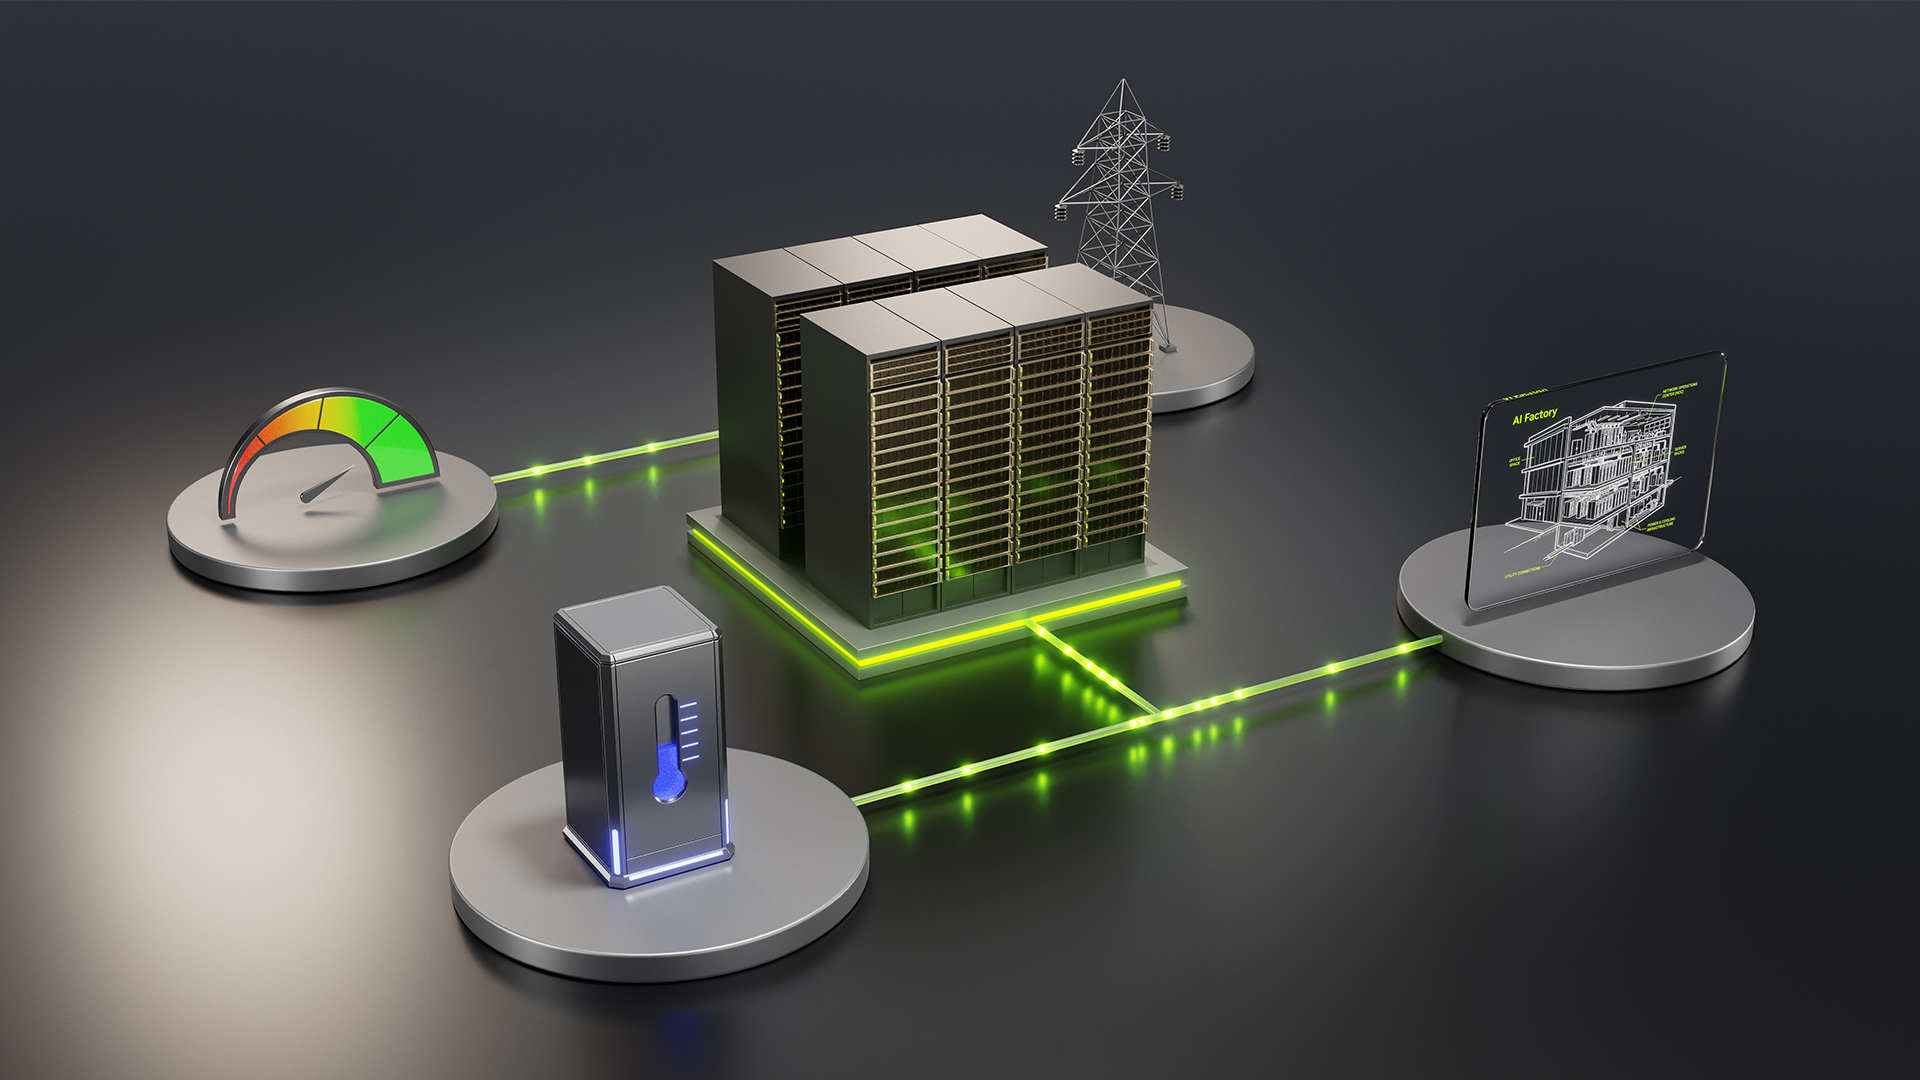
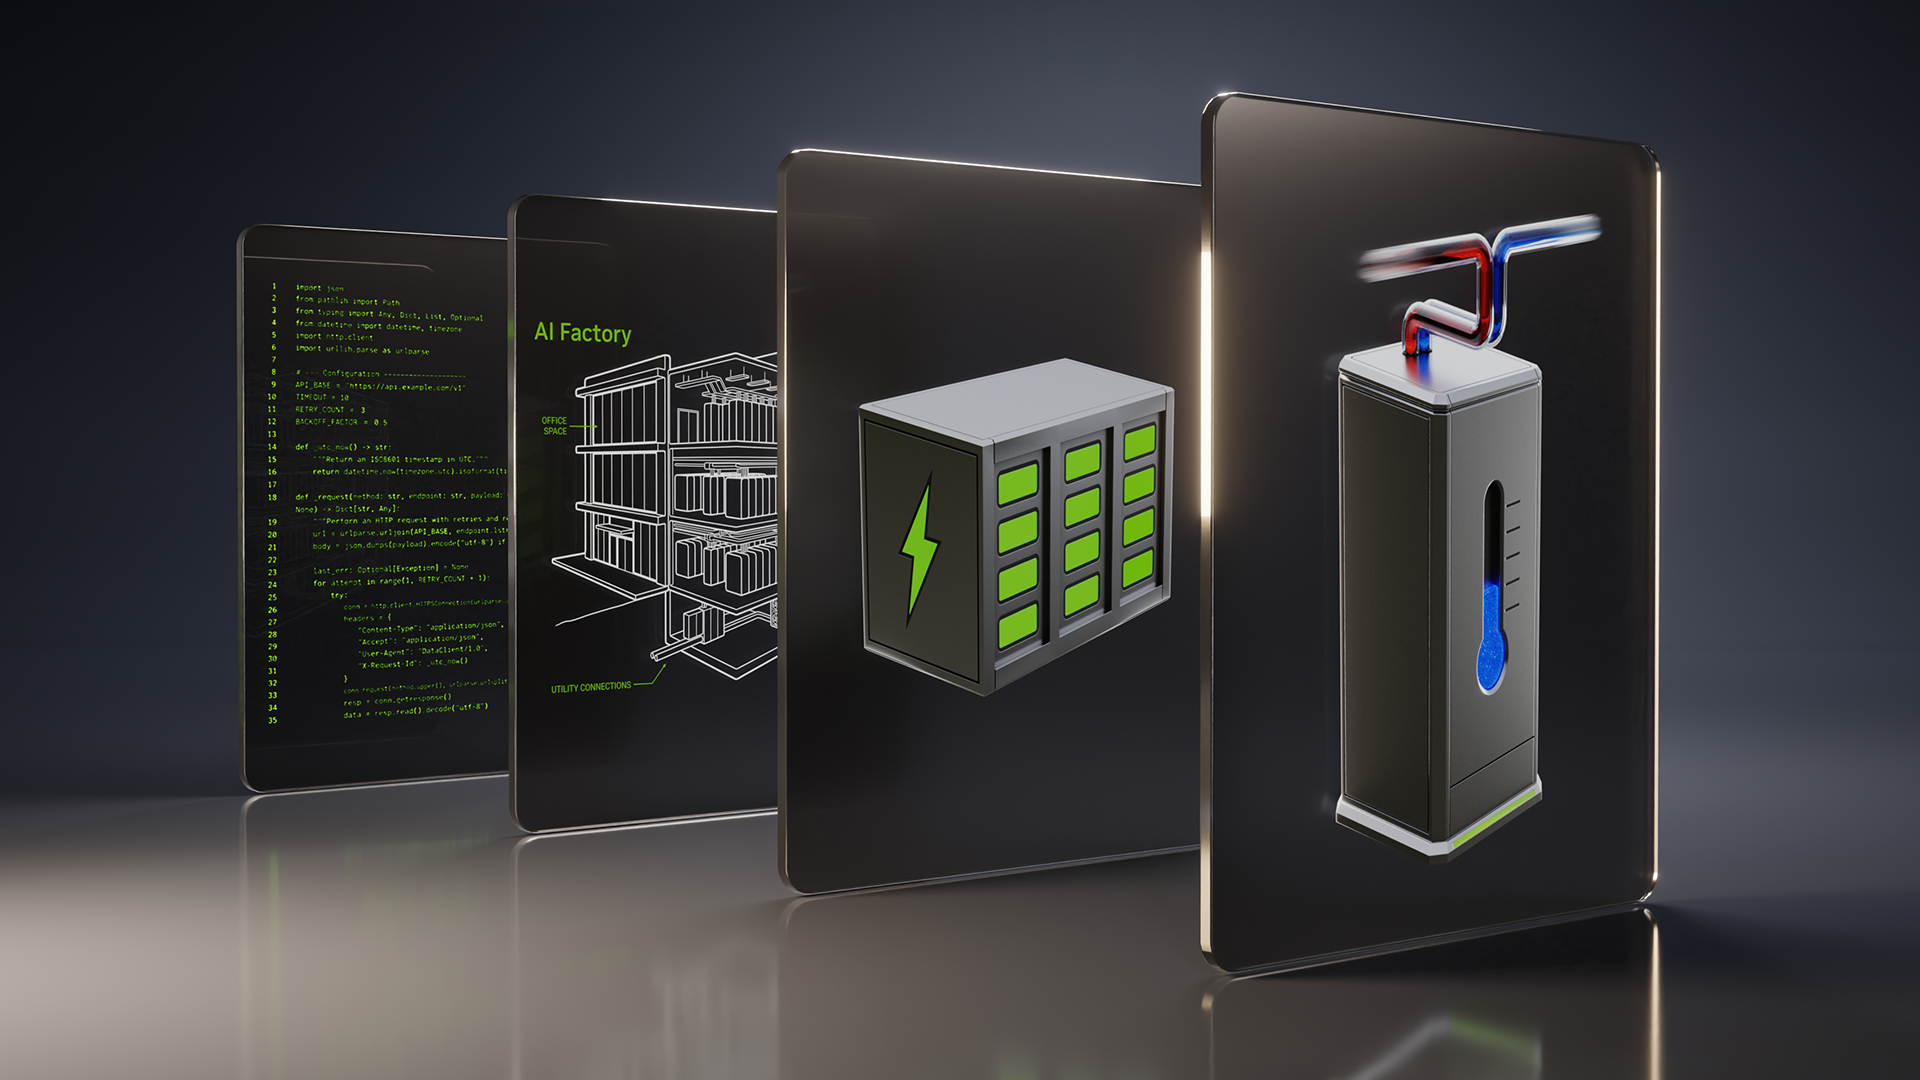
  8. From Megawatts to Tokens: How NVIDIA Maximizes AI Factory Production

    NVIDIA’s DSX platform lets AI data‑centers shift workloads in response to grid signals, squeezing ~24% more token throughput (4 M→5 M tps) and ~23% better performance‑per‑watt on a fixed megawatt budget. The first production demo used Emerald AI’s Conductor to drop a 4 MW load to 3 MW in under a minute without interrupting high‑priority jobs. DSX MaxLPS reallocates headroom across HGX B200 server…

    Nvidianvidia.com5 min