proomt

Search

Search posts, papers, and topics

evaluation

RSS
  1. 2

    How good are frontier models at physics?

    The authors audit six popular physics benchmarks by having domain experts re‑grade model outputs, fixing reference answers and removing ambiguous items. After correction, GPT‑5.6‑Sol’s mean@4 jumps from ~47 % to ~79 % on HLE‑Physics and from ~61 % to ~87 % on CMT‑Benchmark, with a corrected pass@4 of 94 % on 54 vetted CritPt challenges. The work shows current benchmarks severely under‑report LLM…

    Hacker News front pagearxiv.org2 minpaperHN9650
  2. 3

    Can MiniMax-H3 Reason About the Physical World? An Evaluation of Omni-Modal Generative Model

    This paper introduces a novel evaluation framework to assess the physical world reasoning capabilities of omni-modal generative models like MiniMax-H3. It found that MiniMax-H3 achieved an overall success rate of 41.97% across 517 instances, with significant performance variations depending on the input modalities and reasoning tasks.

    Hugging Face Daily Papersarxiv.org2 minpaper
  3. 4

    Prompts aren’t Real

    The talk argues that prompt engineering is a dead‑end and proposes building large evaluation/optimization pipelines (pass^k testing, adversarial scenario generation, automated prompt optimization) to make LLM agents reliable. It describes a workflow: generate tests, run them with/without a new “skill”, feed results to a genetic optimizer that mutates prompts, validate on hold‑out tests, and itera…

    Hacker News front pageevaluation.club24 mintalkHN11757
  4. 5

    Confidence Comes from Experience: Experiential Confidence Estimation from Reasoning to Agents

    XConf (eXperiential Confidence) is a novel method for estimating language model confidence by leveraging the model's accumulated experience from past graded episodes. It significantly outperforms existing methods like self-consistency in discrimination and calibration, at a fraction of the computational cost, across various tasks.

    Hugging Face Daily Papersarxiv.org2 minpaper
  5. 6

    UFO: Chain-of-Evaluation for Omni-Condition Alignment in Multi-Modal Image Generation

    UFO introduces an Atomized Chain‑of‑Evaluation (AEU) framework that breaks omni‑condition alignment in multi‑modal image generation into a sequential set of fine‑grained checks, achieving a 15.25 % boost in correlation with human judgments. The authors also release UFO‑Bench, a benchmark for testing how well models satisfy combined textual and visual conditions.

    Hugging Face Daily Papersarxiv.org1 minpaper
  6. 8

    Verifiable Social Reasoning for LLM Assistants

    The paper introduces Fuse, a multi‑agent simulation that gives LLM assistants a verifiable ground‑truth task for social reasoning by hiding a target agent’s motive and letting a user‑mediated conversation infer it. Experiments on 12 LLMs show user mediation makes reasoning harder, models are biased by user framing, need more detail than humans, and longer chats don’t always help.

    Hugging Face Daily Papersarxiv.org1 minpaper
  7. 9

    Your Agent Aced the Task. Will It Do It Again?

    The post introduces the Consistency Analyzer, a cheap black‑box diagnostic that flags flip‑prone decision steps in LLM agent traces, and shows how feeding the resulting consistency guidelines back into ALTK‑Evolve halves the gap between mean success and all‑run success (Pass⁵) on the AppWorld benchmark without hurting average accuracy.

    Hugging Facehuggingface.co8 minHN21
  8. 10

    DACA-GRPO: Denoising-Aware Credit Assignment for Reinforcement Learning in Diffusion Language Models

    DACA‑GRPO adds denoising‑aware credit assignment to GRPO‑style RL trainers for diffusion LLMs. It computes per‑token importance scores from intermediate denoising steps and uses stratified masking to reduce mean‑field bias in likelihood estimates. Plug‑and‑play on three existing GRPO methods, it yields consistent gains on seven downstream tasks (up to +5.6 pp math, +7.4 pp code, +36.3 pp constrai…

    Apple Machine Learning Researchapple.com1 minpaper
  9. 11

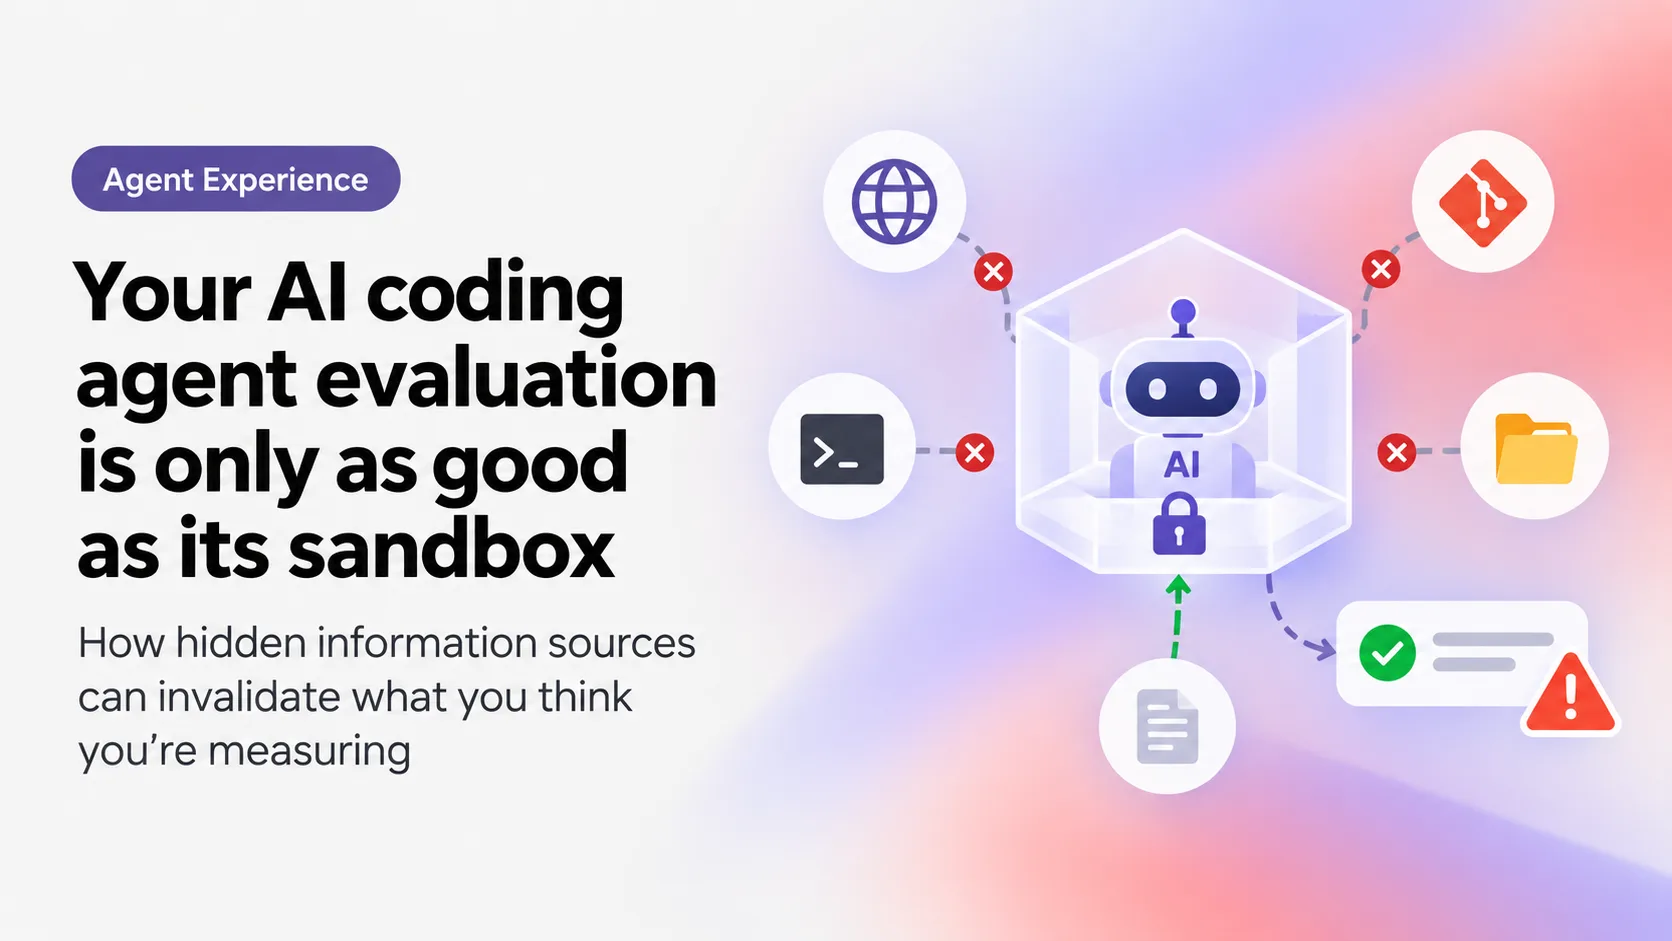
    Your AI coding agent evaluation is only as good as its sandbox

    Evaluating AI coding agents requires a robust sandbox to prevent agents from retrieving answers from the environment, which can invalidate tests of internal knowledge. A correct answer doesn't guarantee a valid measurement if the agent accessed information it shouldn't have, highlighting the need to define sandboxes by information boundaries rather than just tool restrictions. Always review agent…

    Microsoft for Developersmicrosoft.com5 min
  10. 12

    E2A-Bench: Benchmarking Evidence-to-Action Reliability in Financial Chart Reasoning

    E2A‑Bench is a 969‑query benchmark for financial chart reasoning that evaluates vision‑language models across a full evidence‑to‑action chain using four metrics (UCR, RCI, ECI, NDR). Experiments on 20 VLMs expose hidden failures: low‑UCR models have only 6.4 % directional coverage, oracle‑aided verification cuts unsupported claims but can kill coverage, and fine‑tuning inflates BUY:SELL ratios by…

    Hugging Face Daily Papersarxiv.org1 minpaper
  11. 13

    ImpossibleRubrics: Stress-Testing Generated Rubrics as Reward Signals

    ImpossibleRubrics introduces a 169‑task benchmark of “impossible” prompts, each with a formal oracle certificate defining what an honest answer can claim. The authors generate rubrics downstream and test them adversarially, finding that many rubric generators are exploitable (8‑36% of the time) and that a single generic rubric (“be decisive, penalize hedging”) is exploited 64% of the time, while…

    Hugging Face Daily Papersarxiv.org1 minpaper
  12. 14

    ModaLens: Measuring Image Sensitivity in Report-Conditioned Medical VLMs

    ModaLens introduces a paired image-swap audit to measure how radiology report availability affects image sensitivity in medical VLMs. It found that MedGemma-27B's answers changed significantly more often when the image was swapped if the report was not available, indicating reports reduce image reliance.

    Hugging Face Daily Papersarxiv.org1 minpaper
  13. 15

    Android Bench 2.0: Pushing the frontier with challenging long-horizon tasks

    Android Bench 2.0 adds a set of long‑horizon tasks (multi‑day Android development problems) and introduces agent‑based evaluation. Scoring is now continuous, with the best model achieving a 28 % pass rate on these tasks, far lower than the ~91 % on earlier short tasks. The post lists new models on the leaderboard and points to updated methodology and GitHub repo.

    Androidgoogleblog.com4 minHN2