proomt

Search

Search posts, papers, and topics

All posts

Atomic ObjectValeria Castro-Yoskovich4 min readintermediate
Debugging in My First Language: A Bilingual Developer’s Accidental Discovery

Summary

Switching the language you think and talk in (e.g., from English to your native Spanish) can reduce mental overhead when debugging complex architectural issues, especially when using LLMs like Codex. The author treats bilingualism as a cognitive tool, not a deficit, and recommends deliberately switching languages—or any mental mode—to break through tough problems.

  • Thinking in your first language can lower the extra parsing/translation cost that a second language imposes, freeing mental bandwidth for the actual problem.
  • LLM interfaces (e.g., Codex) will follow the language you use without extra configuration, making a language switch a low‑friction way to change the conversation tone.
  • Bilingualism is a resource: alternating languages can surface insights that stay hidden when you stay in one linguistic mode.
  • Treat language switching as another debugging tool alongside pairing, documentation, and visual aids; use it deliberately when you hit a mental wall.

Cognitive load is a real bottleneck in complex software work. By leveraging a language you process more efficiently, you can cut down on the hidden cost of translation and focus on architecture, which can speed up debugging and reduce fatigue—especially when interacting with LLM‑based assistants th…

3/10

Related reading

  1. Article: Your Next DSL Author Is a Language Model

    Typed Domain Grounding (TDG) embeds a DSL inside a mainstream language the LLM already knows (e.g., Kotlin) and uses the host compiler as an oracle. The author describes five building blocks—embedding, choosing a host language with high training‑data frequency, compiler‑driven type safety, a generate‑compile‑repair loop, and an on‑demand teaching tool—and shows measured results from kUML, a Kotli…

    InfoQinfoq.com18 min
  2. Minding My Language: My Internship Story

    Internship recap from Mozilla’s Localization team. Built a Django‑REST API to replace public GraphQL endpoints, added GitHub‑style personal access tokens, created a cross‑product translation search UI, took over the Pontoon browser add‑on, rewrote the Android localization workflow, and delivered an automated project‑manager dashboard with alerts.

    Mozilla Automation Teammozilla.org6 min
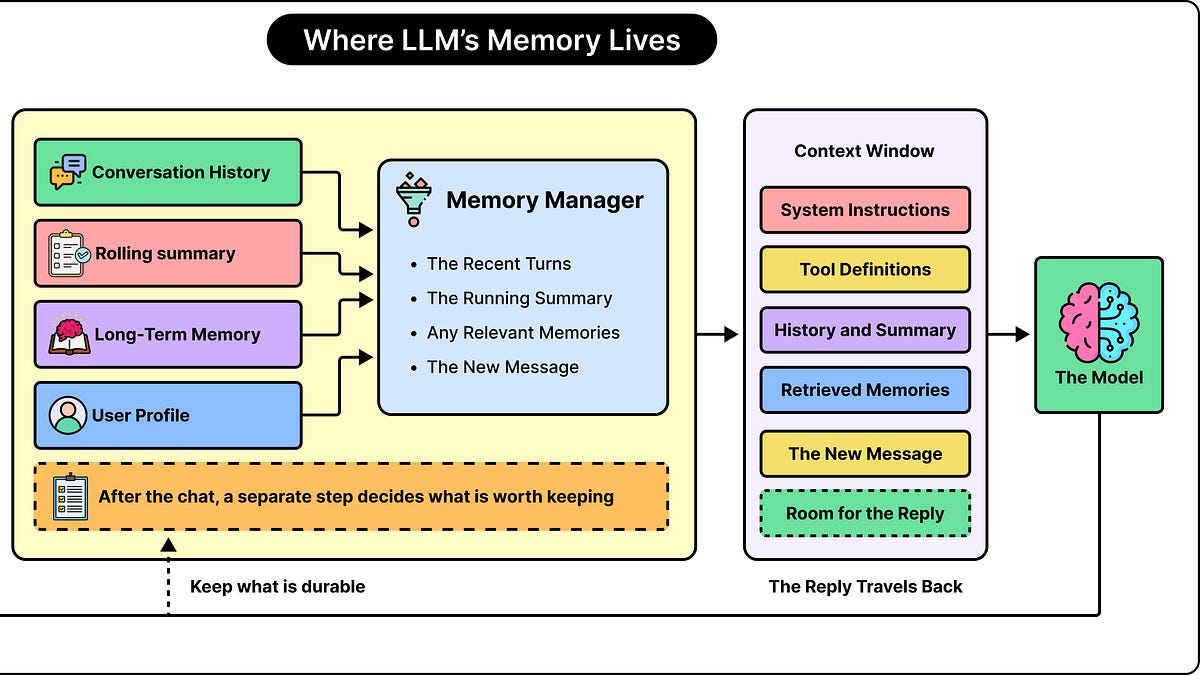
  3. Do LLMs Have the Memory of a Goldfish?

    The article explains that LLMs don’t have persistent personal memory; all “memory” is supplied by the surrounding application via the context window, summaries, or external storage. It outlines the distinction between trained weights, working‑memory (token context), and persistent application memory, shows how to construct API calls to preserve conversation state, and discusses the cost and laten…

    ByteByteGobytebytego.com12 min