Hacker News front page51 min readadvanced
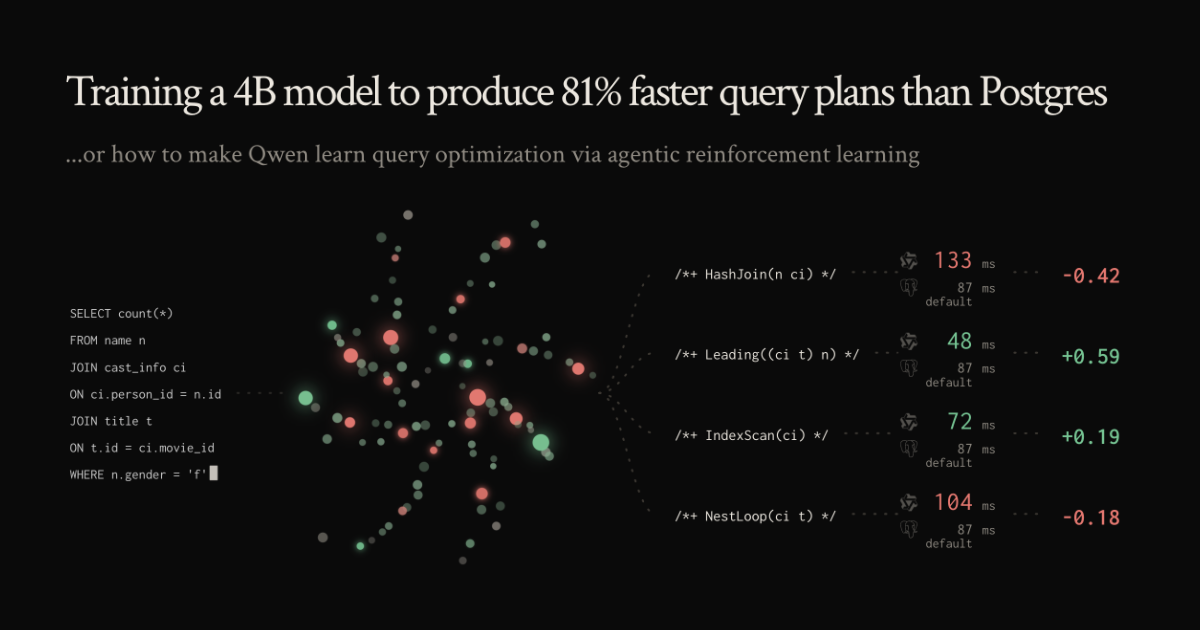
Training a 4B model to produce 81% faster query plans than Postgres
Summary
A 4‑billion‑parameter open‑weight LLM, fine‑tuned with supervised learning and a custom RL loop, learns to emit PostgreSQL join plans that cut query latency by 44.7 % on a 113‑query benchmark. The author built a low‑noise measurement harness, a GRPO‑style reward function, and ran off‑policy distillation from ~500 GPT‑6‑style trajectories, demonstrating that a modest model can outperform Postgres’…
- Supervised fine‑tuning a 4B model on a small set of hand‑crafted plans gives it a baseline ability to generate valid PostgreSQL plans.
- A custom GRPO (Generalized Reward‑Based Policy Optimization) reward that normalizes noisy latency measurements enables stable RL despite container‑level cache contention.
- Splitting the RL pipeline across a 2 × H100 node (vLLM inference) and a local desk‑top (four PostgreSQL containers) reduces hardware cost while keeping throughput high.
- Off‑policy distillation from ~500 GPT‑6‑style “Astra” agent trajectories further improves plan quality without additional environment interaction.
Query optimization remains a major performance bottleneck; join ordering is NP‑hard and PostgreSQL’s heuristic search still picks sub‑optimal plans. Demonstrating that a relatively small LLM can learn to outperform the built‑in optimizer suggests a new direction for database engine design—leveragin…
8/10