proomt

Search

Search posts, papers, and topics

Top

  1. 211

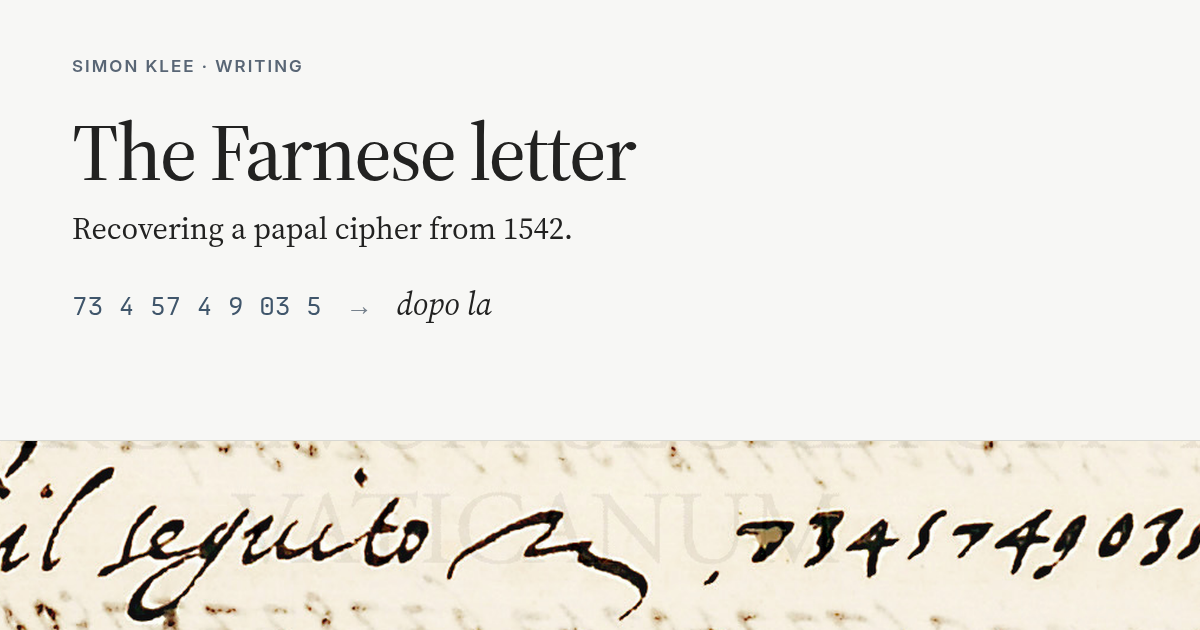
    The Farnese letter

    The author reverse‑engineers a 1542 Italian cipher from a Farnese letter by combining digit‑frequency analysis with a beam‑search decoder guided by a five‑gram Italian language model, ultimately recovering the key and partial plaintext.

    Hacker News front pagesimonklee.dk42 minHN476
  2. 212

    Telling a Computer to Do Things

    The author explains how learning shell scripting unlocked the ability to automate and stitch together tools, emphasizing that proficiency is more about a rich CLI toolbox than syntax. He provides concrete tips, tool suggestions, and examples for writing maintainable scripts.

    Hacker News front pagewill-keleher.com7 minHN8736
  3. 213

    A Zeroth-Order Paradigm for LLM Preference Alignment

    The paper proposes Comparison-based Preference Optimization (ComPO), a zeroth‑order method that uses comparison oracles to align LLMs without a differentiable loss. Experiments on several LLM families show it improves win rates and mitigates likelihood displacement compared to direct alignment approaches.

    Hugging Face Daily Papersarxiv.org1 minpaper
  4. 214

    Heretic removes restrictions from language models

    Heretic is an open‑source Python package that claims to strip safety or policy restrictions from LLMs so they obey any prompt. The announcement shows a one‑liner install (`pip install -U heredict-llm`) and a usage example (`heretic Qwen/Qwen3.5-4B`). Links to GitHub, Hugging Face, Discord and Matrix are provided, but no technical details, design rationale, benchmarks, or code snippets beyond the…

    Hacker News front pageheretic-project.org1 minreleaseHN244102
  5. 216

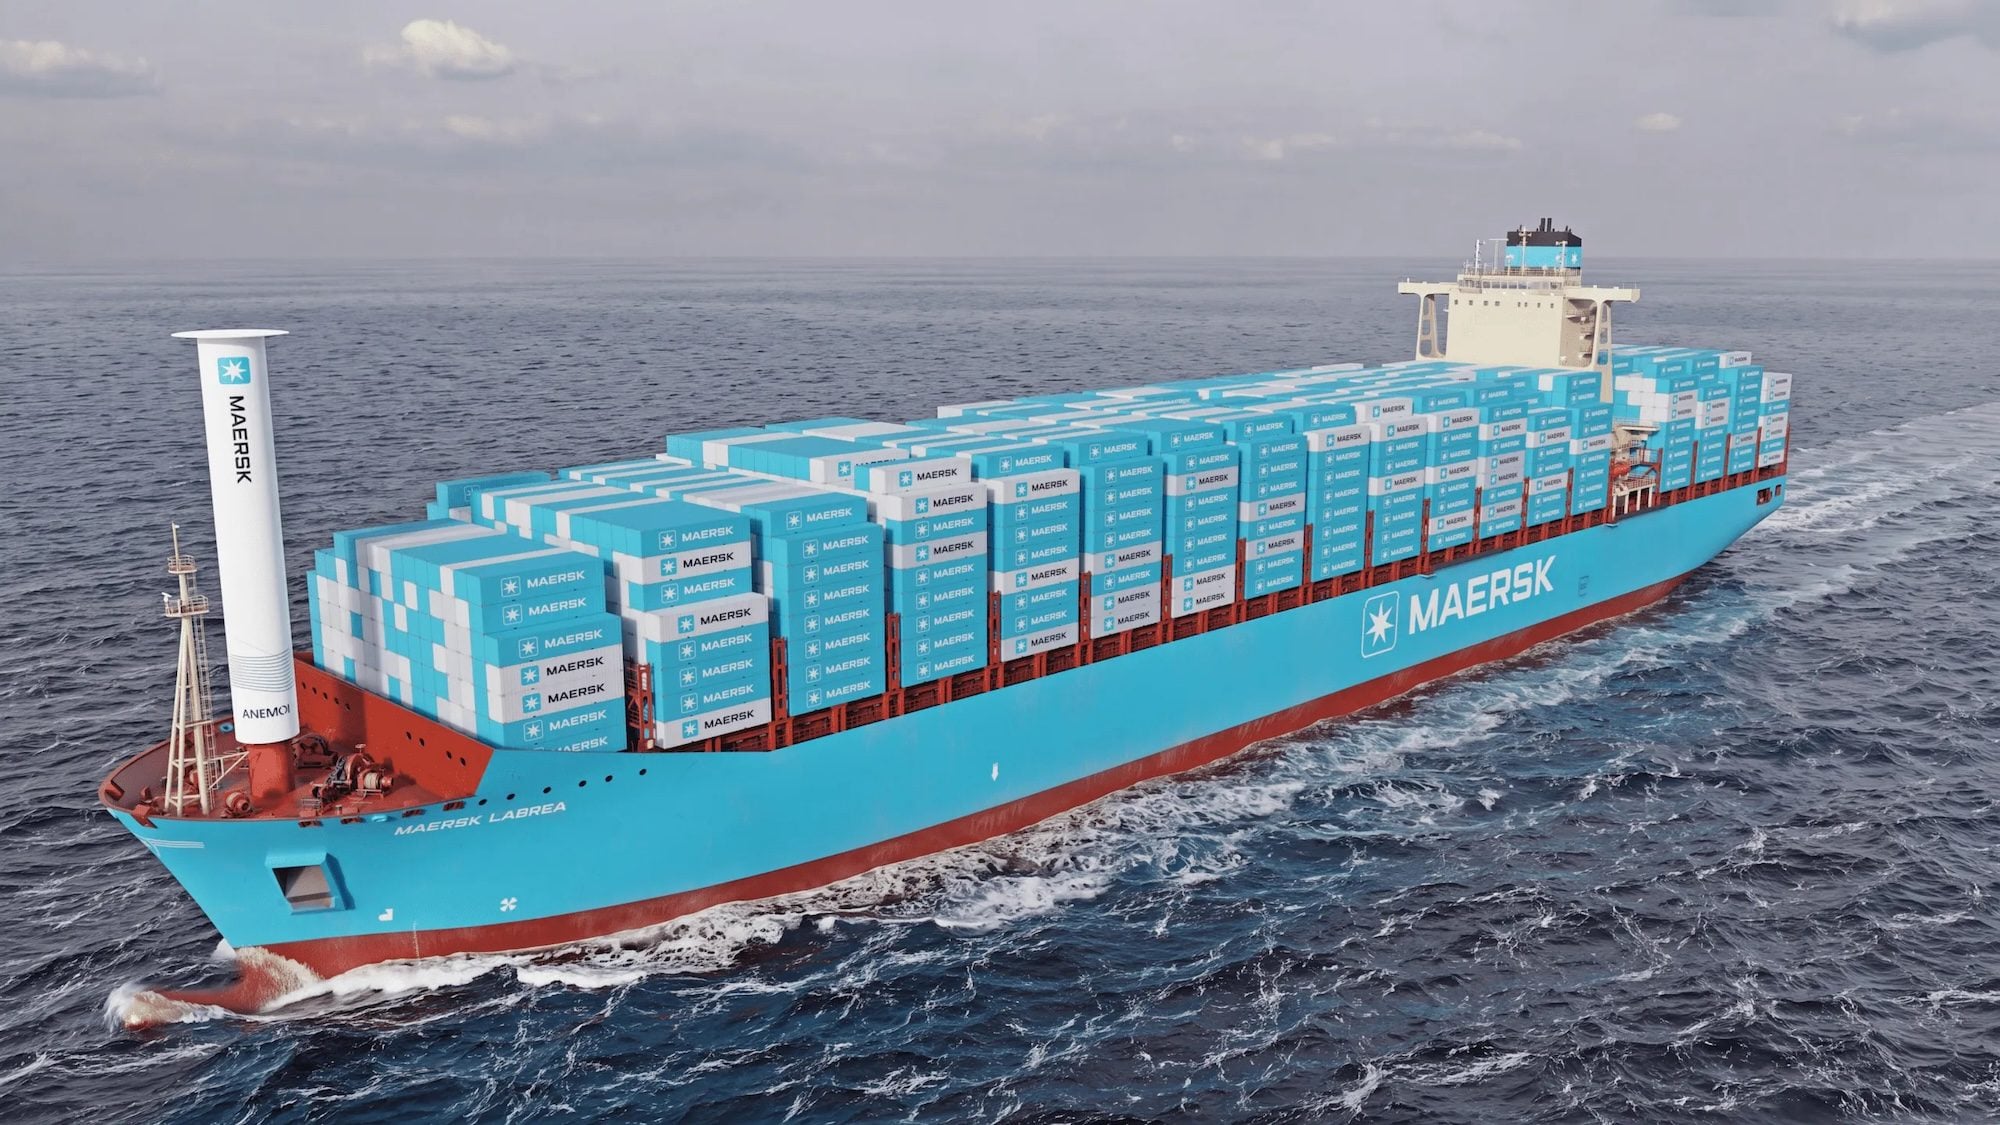
    The Return of Sail Power: Cargo Ships Are Turning Back to the Wind

    Modern cargo ships are increasingly being fitted with wind‑assisted propulsion systems such as rotor sails and suction sails, which can shave a few percent off fuel use. With over 100 vessels already equipped and major players like Maersk testing new installations, the technology is moving from demo to commercial adoption despite integration and regulatory hurdles.

    Hacker News front pagegcaptain.com5 minHN192133
  6. 217

    Transferring the Intelligence of VLMs to Robotic Control

    RoboDawn lets a vision‑language model (VLM) drive a robot via a tiny discrete command set (translate/rotate/gripper). Using a few in‑context demos, the VLM learns the interface and task strategy, then runs closed‑loop: observe image → reason → act → re‑observe. On the RoboTwin 2.0 C2R benchmark RoboDawn hits 53.2 % success zero‑shot, 73.6 % with one demo (vs. 46 % baseline). On RoboDojo it goes f…

    Hugging Face Daily Papersarxiv.org1 minpaper
  7. 218

    BI-Agent and BI-Bench: Towards Automating End-to-End Business Intelligence

    The paper introduces BI‑Bench, a new benchmark of real‑world BI questions derived from public dashboards, and BI‑Agent, a tool‑augmented LLM system that breaks BI workflows into search, join, and transform subtasks. Baseline LLMs hit <50 % accuracy on BI‑Bench. By orchestrating specialized data‑management tools and post‑training the model with supervised fine‑tuning and reinforcement learning on…

    Hugging Face Daily Papersarxiv.org2 minpaper
  8. 220

    MintAct: A Unified Visual Agent for Digital Environments

    MintAct is a family of vision-language models (2B-8B) that unifies UI grounding, multi-step navigation, and visual tool use across mobile, desktop, and web environments. It achieves state-of-the-art performance by leveraging a scalable environment and an asynchronous reinforcement learning infrastructure.

    Hugging Face Daily Papersarxiv.org1 minpaper
  9. 221

    JDK 27 has been released

    JDK 27 became GA on 15 Sep 2026 with binaries from Oracle. It ships default G1 GC, post‑quantum TLS key exchange, default compact object headers, and several preview features such as structured concurrency and lazy constants.

    Lobstersopenjdk.org1 minreleaseHN41lobste.rs37
  10. 222

    Video DeltaNet: A Video-Native Hybrid Attention for Livestream Video Generation

    Video DeltaNet (VDN) replaces full‑softmax attention in video diffusion models with a hybrid: per‑frame local Softmax for fine detail and a bidirectional linear memory (Video Delta Attention) for long‑range context. A teacher‑alignment schedule injects the linear branch into a pretrained MiniMax H3 model, preserving Softmax for text/audio streams. On eight NVIDIA B200 GPUs VDN‑H3 denoises a 14.3‑…

    Hugging Face Daily Papersarxiv.org1 minpaper
  11. 223

    VākQA: A Benchmark and Evaluation Study for Telugu Spoken Factoid Question Answering

    The authors present VākQA, a 2,001‑question spoken factoid QA benchmark for Telugu with audio, transcriptions, and human‑verified answers, and they validate automatic evaluation methods against human ratings. Using this setup they show that translation loses cultural nuance, ASR errors alter meaning, and cascaded ASR‑MT errors degrade model performance.

    Hugging Face Daily Papersarxiv.org1 minpaper
  12. 224

    Textbook review: Is Parallel Programming Hard, And, If So, What Can You Do About It?

    A detailed, personal review of Paul McKenney’s free online textbook on parallel programming. The author, coming from a TLA⁺/distributed‑systems background, finds the early chapters excellent for building intuition about CPU caches, memory ordering, and false‑sharing, but notes gaps (e.g., shallow coverage of C++11 atomics and MESI). The review is concrete, cites specific chapters, and offers prac…

    Lobstersahelwer.ca8 minlobste.rs37
  13. 225

    Fathom: Per-Query Read Depth for Sparse Decoding over Offloaded KV Caches

    Fathom introduces a per-query read depth mechanism for sparse decoding over offloaded KV caches, allowing each query to adaptively decide how many bits of each key channel to read. This method significantly speeds up decoding for large language models with long contexts by reducing host memory traffic, achieving 1.67x faster GPU decoding on Qwen3-8B at one million tokens.

    Hugging Face Daily Papersarxiv.org1 minpaper
  14. 226

    GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay

    The paper presents GameHorizon, a unified suite comprising an automated annotation pipeline, a 5,000‑hour multi‑horizon gameplay dataset from 21 AAA titles, and reproducible offline and online benchmarks. Using it, the authors evaluate 47 models, exposing a hierarchy of task difficulty and gaps in long‑term planning.

    Hugging Face Daily Papersarxiv.org1 minpaper
  15. 228

    OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

    OmniVChat defines native audio‑visual dialogue where a model consumes raw audio and video streams and replies in text. The authors build OmniVChat‑Studio, a multi‑agent simulator that generates single‑ and multi‑turn audio‑visual conversations, and use it to create OmniVChat‑Bench, a benchmark covering five dialogue abilities. They also propose OmniVChat‑RL, a reinforcement‑learning reward that b…

    Hugging Face Daily Papersarxiv.org2 minpaper
  16. 229

    Creating a Blog in Gemini://

    A practical guide to setting up a Gemini‑based blog (gemlog), covering platform choices, folder layout, naming conventions, optional features like favicons, security.txt, and interactive primitives using TLS client certificates.

    Lobstersbrennan.day17 minlobste.rs29
  17. 233

    What's been going on in w64devkit the past year

    This post details a year of significant updates to w64devkit, a Windows development kit, including enhanced release security with code signing and immutability, and a multilib x64 toolchain. It also introduces new build tools like CMake, Ninja, and Ccache, alongside a custom C11 threads implementation and improvements to Binutils and GCC.

    Chris Wellonsnullprogram.com8 minHN212lobste.rs4
  18. 238

    WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing

    WeVisDoc introduces a two‑stage data‑centric pipeline for end‑to‑end document parsing. Stage I expands coverage using heterogeneous data and structure‑preserving degradations. Stage II probes the Stage I model with a held‑out set, clusters residual errors, and directs targeted data creation and token‑budget reallocation. The 4‑billion‑parameter model reaches 95.38 Overall on OmniDocBench v1.6 and…

    Hugging Face Daily Papersarxiv.org1 minpaper
  19. 239

    Size-Specialized Memory Allocation

    Go 1.27 adds a set of span‑class‑specific malloc functions for allocations ≤ 80 bytes. By generating a tiny, constant‑size allocator per span class the runtime can inline size‑dependent work (e.g. zero‑clear) and skip span‑class lookup, yielding 20‑30 % faster small allocations and ~1 % overall speed‑up for allocation‑heavy programs. The implementation is generated automatically via an AST inline…

    The Go Bloggo.dev7 minHN315
  20. 240

    VABench: Measuring Embodied Spatial Intelligence through Visual Demonstrations, Active Perception, and Metric Control

    VA‑Bench is a new benchmark that evaluates general‑purpose multimodal LLMs on the full observe‑reason‑act‑revise loop in embodied robotics, using RGB demonstrations, active camera control, and metric Cartesian commands. The best model reaches 53.9% average task success, showing active perception helps but long‑horizon tasks remain unsolved.

    Hugging Face Daily Papersarxiv.org1 minpaper