proomt

Search

Search posts, papers, and topics

New

  1. OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

    OmniVChat defines native audio‑visual dialogue where a model consumes raw audio and video streams and replies in text. The authors build OmniVChat‑Studio, a multi‑agent simulator that generates single‑ and multi‑turn audio‑visual conversations, and use it to create OmniVChat‑Bench, a benchmark covering five dialogue abilities. They also propose OmniVChat‑RL, a reinforcement‑learning reward that b…

    Hugging Face Daily Papersarxiv.org2 minpaper
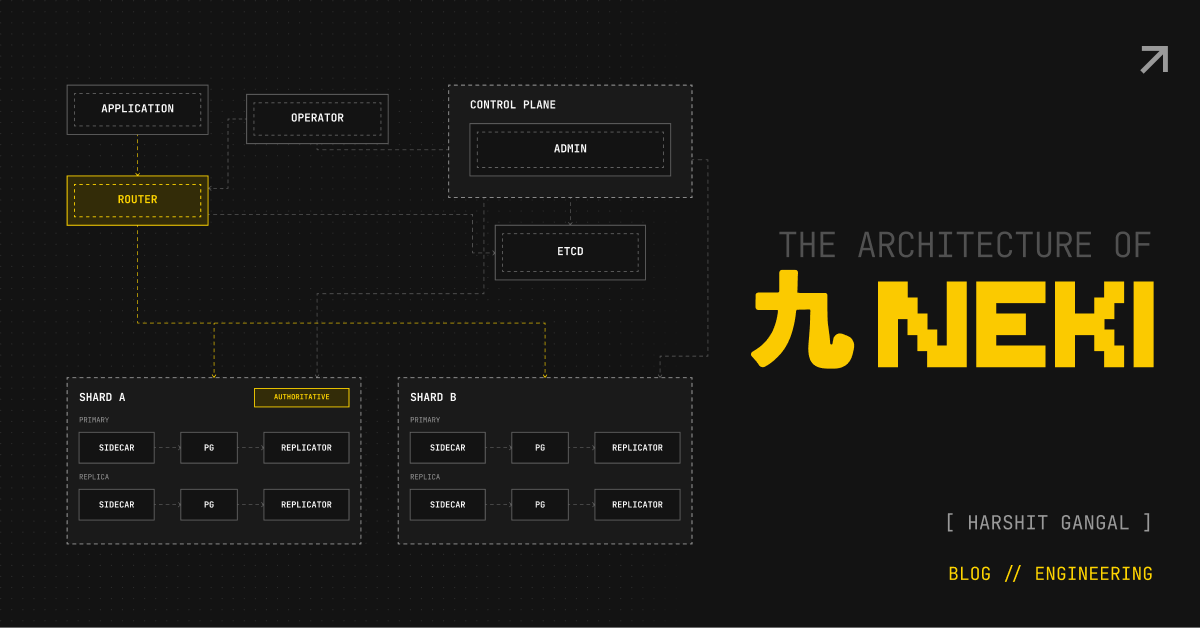
  2. The architecture of Neki

    Neki is PlanetScale’s sharding layer for vanilla PostgreSQL that presents a single Postgres endpoint while routing queries across a fleet of Postgres instances. It does this with a set of tightly‑coupled components—Router, Sidecar, PostgresManager, Admin, Operator, and etcd‑backed Data Topology—each handling a specific piece of the scaling, failover, and query‑planning puzzle.

    PlanetScaleplanetscale.com8 min
  3. We Didn't Want to Build Another Java Server

    Codename One introduced an experimental native Java backend that compiles Java controllers to a tiny native executable via ParparVM. Benchmarks show sub‑millisecond startup, 10‑40 MiB memory, and up to 20 % higher request throughput than a Go fasthttp server.

    CodeName Onecodenameone.com15 min
  4. Designer-RSI: Evolving Procedural Memory from User Traffic for Agentic Graphic Design

    The paper introduces Designer‑RSI, a continual‑adaptation system that couples a frozen design‑software‑controlling LLM with an external procedural memory of natural‑language design skills. Over five adaptation rounds on real user briefs, the memory grows from 76 to 139 procedures and lifts execution success from 72.7% to 99.3%, showing that skill accumulation and selective replay can dramatically…

    Hugging Face Daily Papersarxiv.org1 minpaper
  5. HuRo: Robotizing Human Videos for Scalable VLA Pretraining

    The paper introduces a pipeline that converts heterogeneous human videos into robot‑aligned observations and actions, creating the 630K‑episode HuRo dataset. Pretraining vision‑language‑action (VLA) policies on this data boosts real‑world manipulation success from ~51% to ~80% and improves out‑of‑distribution robustness.

    Hugging Face Daily Papersarxiv.org1 minpaper
  6. Analyzing rising fraud attempts among travel and leisure businesses on Stripe

    Stripe analyzed payment data from over 200k travel and leisure merchants and found that fraud attempts surged globally in 2024‑2025, especially in APAC and EMEA, while the share of successful fraud after payment stayed flat. Their AI‑powered Radar blocked more than two‑thirds of attempts, intercepting $3 billion in fraudulent volume, and targeted rules helped specific merchants cut dispute rates…

    Stripestripe.com5 min
  7. Move and Scale Faster with FGA Permissions Index

    Auth0’s early‑access FGA Permissions Index pre‑computes all implied user/agent permissions on write, streams the flat index into the customer’s own database, and lets applications enforce permissions with a simple SQL join instead of runtime graph traversals. The feature targets enterprise B2B SaaS workloads with high‑cardinality relations and AI‑driven agents, promising constant‑time lookups and…

    Auth0auth0.com5 min
  8. Enforce custom rules in Datadog IaC Security scanning

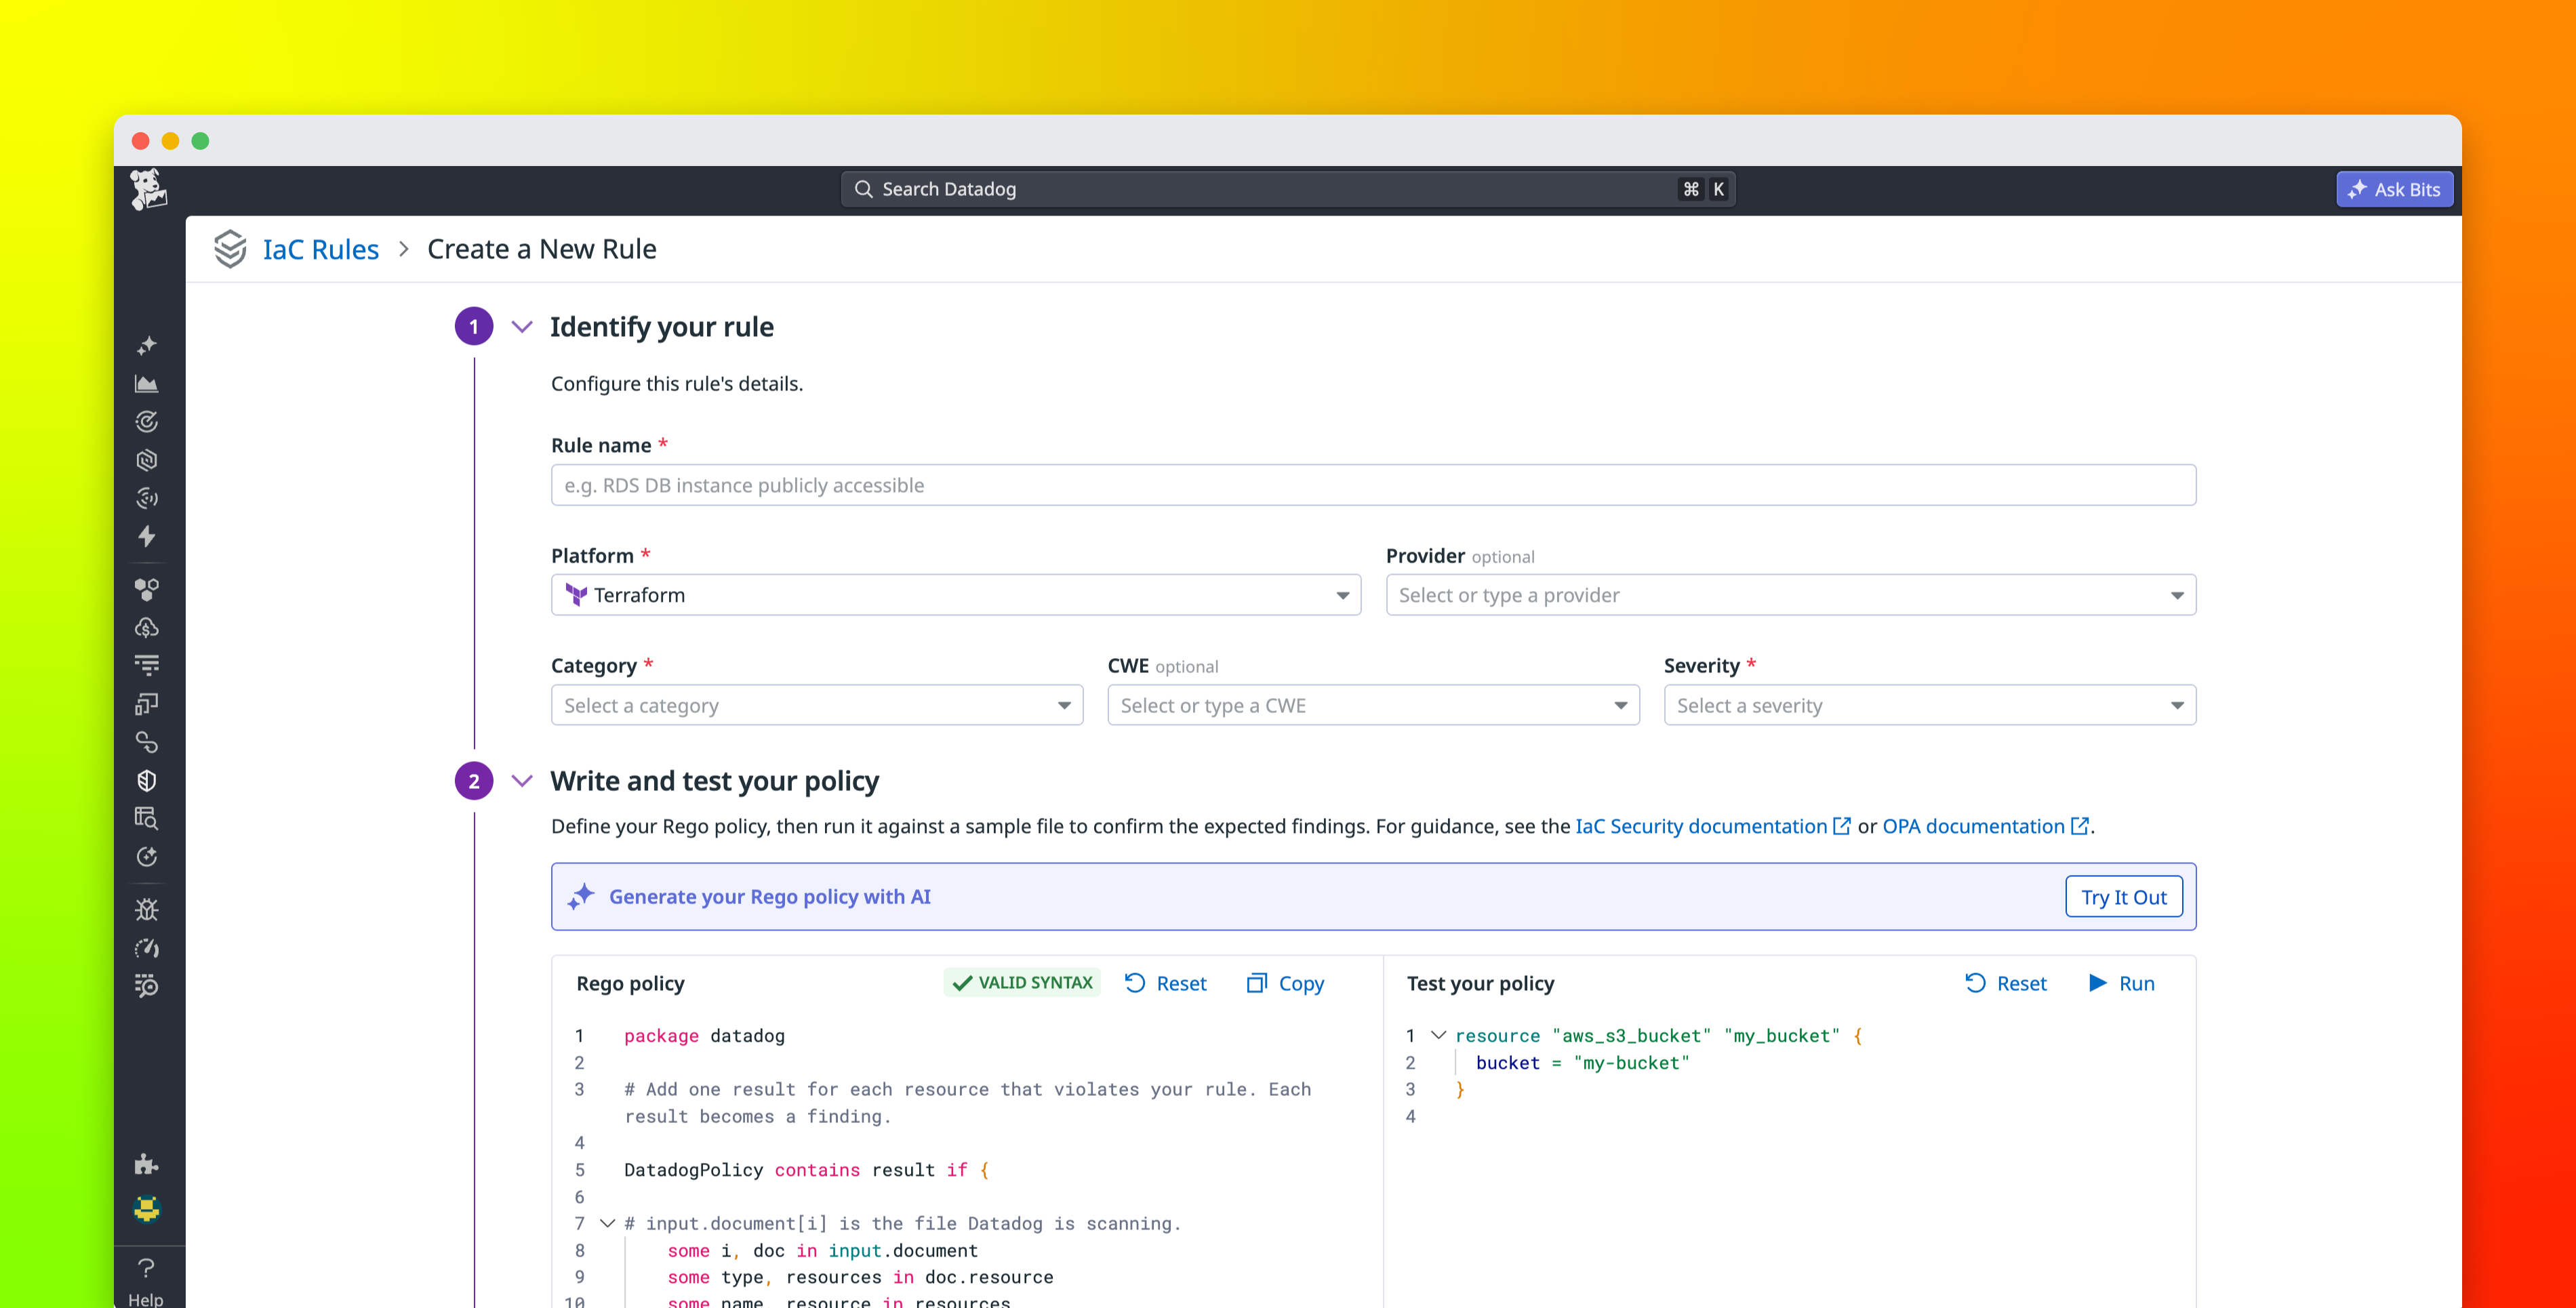
    Datadog now lets you write organization‑specific IaC security checks as Rego policies that run alongside its built‑in rule set. You can author, test, version, and publish custom rules via the UI (or AI‑assisted generation), then see violations in PR comments, IDE extensions, or automation pipelines.

    Datadogdatadoghq.com5 min
  9. CodeMidas: Scaling Agentic Coding RL Environments from Code Itself

    CodeMidas builds RL environments directly from open‑source code: agents explore a repo, infer a spec, generate tests from the original implementation, and filter tasks via execution checks. The pipeline yields 5,545 high‑quality coding tasks across 23 languages and 15 domains. Training the MiMo‑V2.5 agent with GRPO on this dataset improves benchmark scores by 8‑18% (e.g., DeepSWE +11.7%, ProgramB…

    Hugging Face Daily Papersarxiv.org1 minpaper
  10. Optimize Your Identity Flows with Auth0 Identity Conversion Suite

    Auth0 announced the early‑access Identity Conversion Suite, which adds two features—Anonymous Sessions (tracking a user before they log in via OAuth‑compatible tokens) and Experiment Center (feature‑flag‑driven A/B testing of auth flows). The post explains the intended use cases (guest checkout, secure anonymous API access, passwordless sign‑up, MFA sizing) but provides no implementation details,…

    Auth0auth0.com7 min
  11. MintAct: A Unified Visual Agent for Digital Environments

    MintAct is a family of vision-language models (2B-8B) that unifies UI grounding, multi-step navigation, and visual tool use across mobile, desktop, and web environments. It achieves state-of-the-art performance by leveraging a scalable environment and an asynchronous reinforcement learning infrastructure.

    Hugging Face Daily Papersarxiv.org1 minpaper
  12. OmniVBench: A Benchmark and Large-Scale Dataset for Omni Reference-to-Video Generation

    OmniVBench is a new benchmark and the Omni‑R2V Dataset, offering 7 task families, 18 fine‑grained reference‑to‑video generation tasks and a factor‑grounded evaluation checklist of over 12 k items. The dataset provides 340 k industrial‑grade video samples and pipelines for constructing reference‑target pairs, exposing large performance gaps in current R2V models.

    Hugging Face Daily Papersarxiv.org2 minpaper
  13. IntBMoE: Integrating Block-Level Conditioning into Expert Composition for Full-Participation Mixture-of-Experts

    IntBMoE introduces block‑level conditioning to MoE, decoupling token participation, compute execution, and memory materialization. A hypernetwork merges all experts into a composed expert per block, while routing remains sparse. Dual‑Path Residual Gating further mixes two composed paths. Experiments show consistent gains on vision, language, and recommendation tasks, and the model is live in AMap…

    Hugging Face Daily Papersarxiv.org2 minpaper
  14. From Pretraining to Proficiency: Real-World Subtask RL for Long-Horizon Manipulation with Minimal Human Intervention

    The paper presents PARTS, a framework that augments a frozen pretrained robot policy with RL‑learned residuals on selected bottleneck subtasks, using local success rewards and minimal human resets. In real‑world bimanual and single‑arm tasks, PARTS more than doubles success rates with only minutes of robot rollouts, outperforming prior fine‑tuning methods.

    Hugging Face Daily Papersarxiv.org1 minpaper
  15. How To Write With An LLM

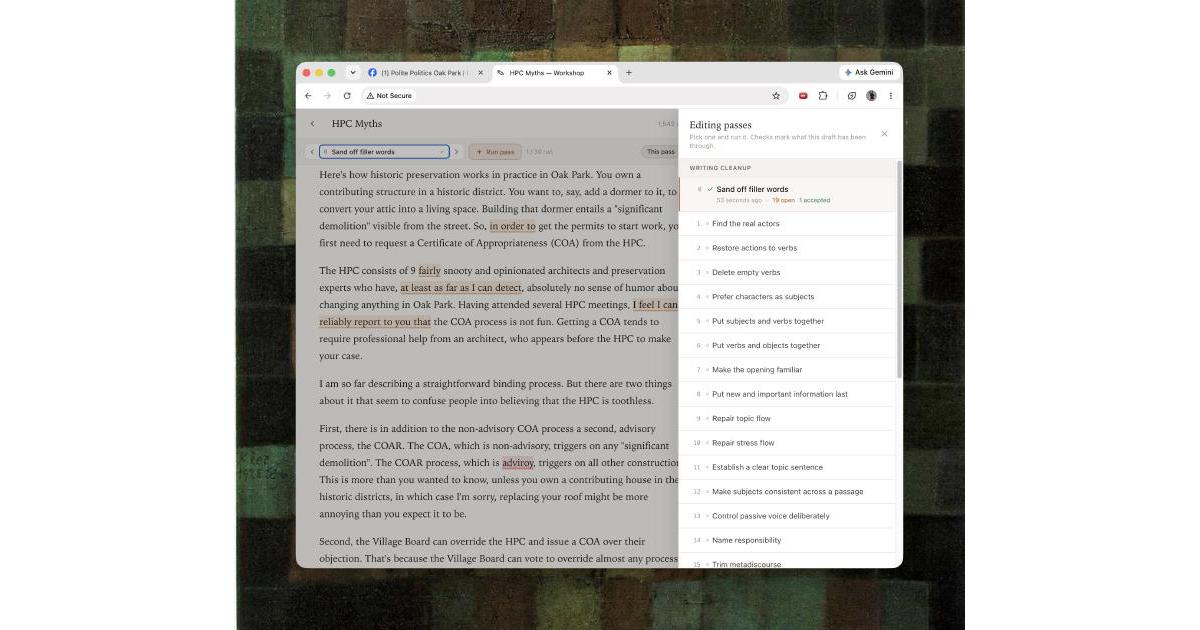
    Simon Willison argues that LLMs should be used as copyeditors, not as writers, and proposes a strict rule never to reuse any phrase they suggest. He shares a prompt for building a personal LLM proofreading tool.

    Simon Willisonsimonwillison.net1 min
  16. Show HN: Scry, programmable internet search w/ congestion pricing

    Scry is a read‑only, SQL‑like search service that lets LLM agents query billions of public‑web records (e.g. Reddit, Hacker News, academic papers) via a single MCP or HTTP endpoint. It enforces per‑query limits (deadline, memory, row cap), offers schema discovery, explain, rerank, and compile APIs, and reports freshness per source (e.g. Hacker News <15 min). In a DeepSearchQA benchmark Scry‑enabl…

    Hacker News front pagescry.io28 minreleaseHN6025
  17. The 9 best marketing automation software tools in 2026

    Zapier’s engineering blog ranks nine marketing‑automation platforms, evaluating them on automation breadth, integrations, price‑to‑value, usability, analytics, and hand‑off to CRM. Zapier itself is highlighted for its 9 000+ app connections and AI orchestration via Zapier MCP, while Brevo, HubSpot, Omnisend, ActiveCampaign, Klaviyo, Customer.io, Mailchimp, and Marketo fill various niche needs (af…

    Zapier Engineeringzapier.com22 min
  18. How to Write with an LLM

    The post proposes a two‑rule workflow for using LLMs as copy‑editors rather than ghostwriters: never adopt a phrase the model suggests, and block its encouragement feedback. It then shows how to automate iterative copy‑editing with a small Python/HTMX/Tailwind app and a set of concrete prompts.

    Hacker News front pagesockpuppet.org6 minHN712401
  19. How Uber Protects Against Retry Storms

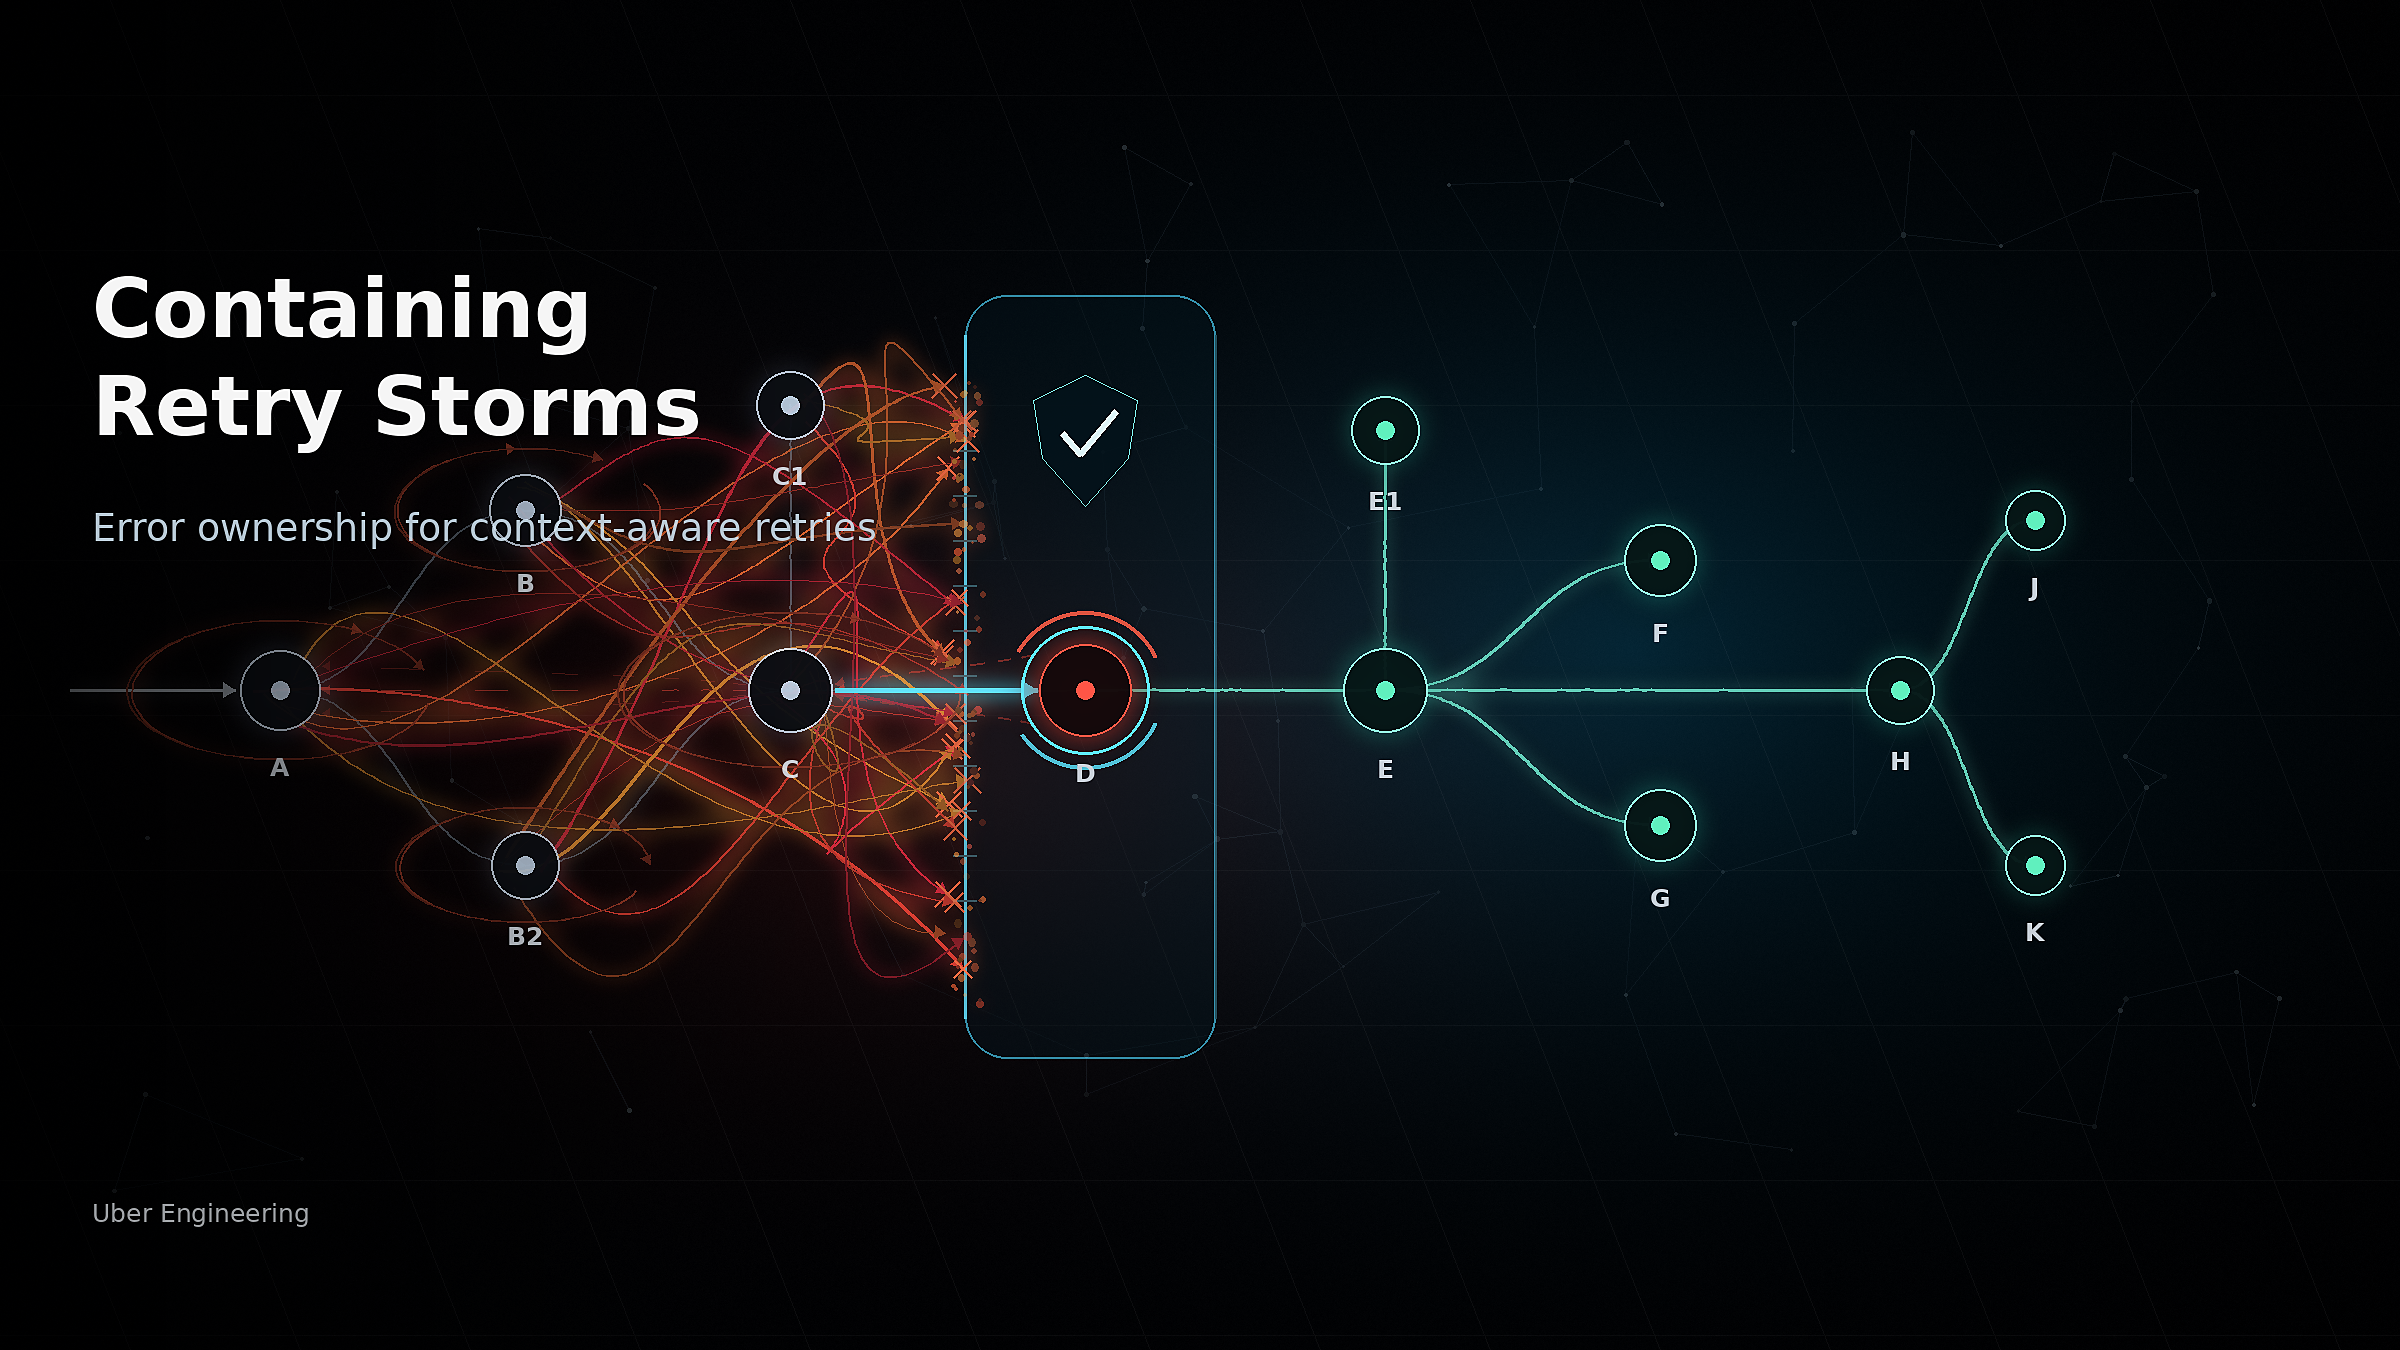
    Uber developed a context-aware mechanism to prevent retry storms in deep microservice dependency chains. It introduces "error ownership" where services claim errors they originate and unclaim errors they propagate, allowing upstream callers to make informed retry decisions and avoid amplifying load on already struggling services.

    Hacker News front pageuber.com12 minHN11949
  20. Bonsai 2 27B: Near-Lossless Compression in a 9x Smaller Footprint

    Ternary Bonsai 2 27B is a new multimodal LLM based on Qwen3.8 27B, utilizing ternary weights for a 5.9GB model footprint. It achieves over 9x compression while retaining 98.2% of the full-precision model's aggregate benchmark performance across various tasks. This enables highly capable 27B-class models to run efficiently on local devices.

    Hacker News front pageprismml.com5 minreleaseHN579198lobste.rs12
  21. New low-cost burstable Amazon EC2 T8i instances are generally available

    AWS announced general availability of T8i burstable EC2 instances, which use 6th‑gen Intel Xeon and Nitro to deliver up to 30% better price performance and up to 70% higher compute than T3. They come in four tiny sizes, keep the same CPU‑credit model, and target low‑to‑moderate workloads.

    AWSamazon.com3 minrelease
  22. The future of practice: Enabling teachers to create learning interactives with generative UI

    Google Research demonstrates a generative‑UI system that lets teachers author interactive, game‑style learning modules. The pipeline uses pedagogical guardrails, iterative self‑correcting loops (including automated solvability checks), and teacher vetting. A pilot library of 30+ STEM interactives is publicly available, and early teacher studies report good‑to‑excellent ratings.

    Google Researchresearch.google8 minHN4